
Kimi K3.1 Pro Tests the Case for Open Frontier Models
Executive Summary
Frontier-level capability is becoming a more credible prospect for users who want control of model weights—but the release decision increasingly includes control of offensive capability. Moonshot’s Kimi K3.1 Pro announcement combines competitive benchmark results with an explicit argument for gradually widening access to cybersecurity capabilities. The model is available through hosted products and APIs; full weights are promised by November 4, not available yet.
The independent evidence supports taking the capability claim seriously: Artificial Analysis scores it at 55 on its Intelligence Index. That does not establish universal parity with proprietary leaders, affordable self-hosting, or safe deployment. The substantive development is a capable model approaching a weight release, accompanied by unusually concrete disclosure of what its developer tried—and failed—to remove from its cyber capabilities.
What Happened
Launched on October 23, K3.1 Pro is a post-trained version of Kimi K3. Moonshot attributes the gains to substantially increased post-training compute, joint reinforcement learning across hundreds of domains, and improvements to the infrastructure supporting that training. It advertises a one-million-token context window and improvements in coding, financial research, and 3D creation.
One concrete result: Moonshot reports 65.7% on Terminal-Bench 4.0, compared with 66.4% for Claude Opus 5.5 and 58.2% for GPT-6 Astra. These are vendor-reported comparisons, not a fresh independent head-to-head experiment. Its footnotes also matter: Kimi uses the Claude Code harness, most results use maximum reasoning effort, and comparison scores draw on other publications and leaderboards. The numbers describe evaluated systems and conditions, not model ability detached from its surroundings.
Artificial Analysis provides a separate check on the broader capability story. Its evaluation also complicates the price story: the model is described as very verbose and slower than average. Listed API prices are $2 per million input tokens and $10 per million output tokens. Simon Willison’s hands-on account reports a Highspeed option offering two to three times the speed at twice the price, except for cached input. Cheaper tokens and faster completion are different purchasing decisions; neither alone measures cost per successful task.
The Release Decision Is Part of the Model Story
Moonshot’s cybersecurity disclosure is the most consequential part of the announcement beyond the scores. It says vulnerability-research capability increased as post-training scaled, including through cyber-related material embedded in broad training data and reinforcement-learning environments.
The company reports removing cyber-related data from both mid-training and reinforcement learning. On its internal xdev-bench-hard evaluation, an unfiltered checkpoint solved 90.5% of tasks at pass@3; the final model solved 81.0%. These are company-reported results on its own benchmark. They are not an estimate of success against arbitrary real-world targets.
The narrower finding is important: targeted filtering reduced measured capability but did not erase it. Moonshot explicitly says stronger general coding and long-horizon debugging continued to generalize to cyber tasks. It argues for releasing weights that remain below the absolute cyber frontier while progressively increasing what defenders can access.
That is a release philosophy, not independent proof of safety. The same disclosure supports both the defensive-access argument and concern about wider availability of dual-use capabilities.
The Bigger Story
Yesterday’s discussion of Agent Skills separated portable procedural knowledge from dependable execution. Kimi adds another distinction: access to strong weights is separate from the infrastructure, evaluation conditions, and safeguards that make those weights useful in practice.
The near-term test is therefore twofold: whether the promised weights arrive with usable terms, and whether independent users reproduce useful performance at acceptable operating cost. Until then, “open-weight frontier competitor” describes a plausible destination, not a completed deployment option.
Further Reading
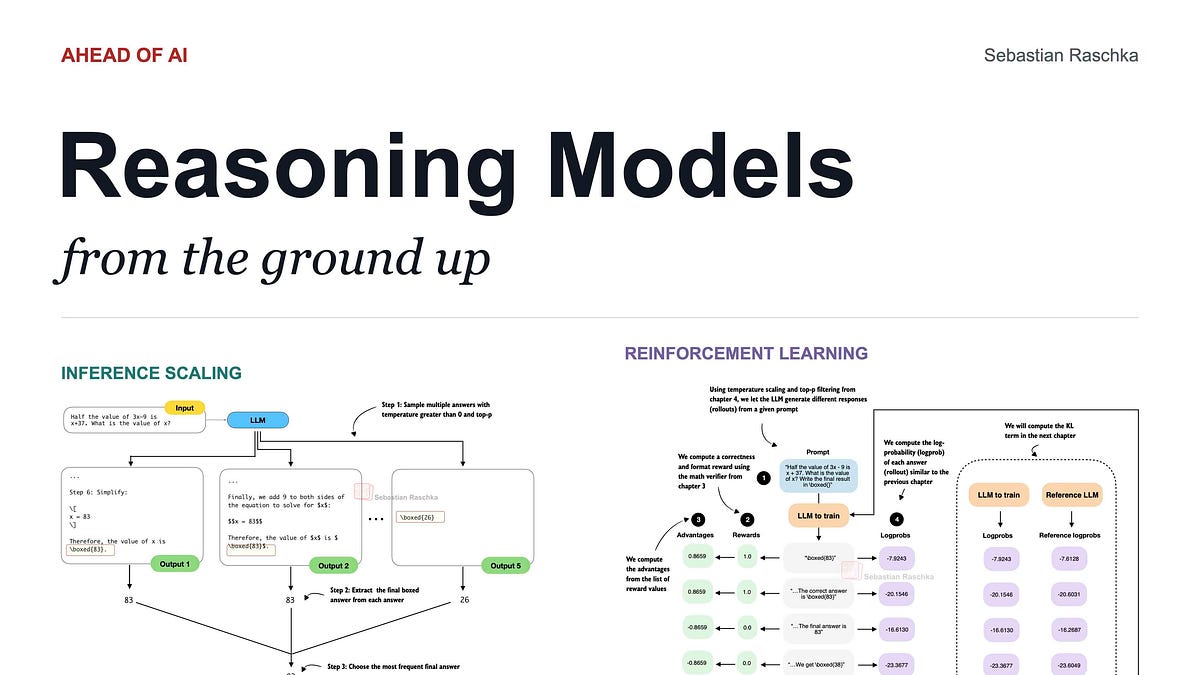
- Sebastian Raschka: Build Your Own Reasoning Model — Eight coding videos covering evaluation, inference-time scaling, reinforcement learning, and distillation. A substantial technical companion to the post-training claims, starting from a small pretrained Qwen3 model rather than training a base model from scratch.