AI Digest archive
AI Digest August 2026
18 digest entries from August 2026, covering 01 Aug 2026 to 25 Aug 2026.
Topic signals
agentsevaluationworkflow-designdeveloper-workflowsai-researchmodel-routing
Archive entries
Agent Reliability Is Becoming a System Design Problem
A reproducible billing-triage example argues that agent reliability improves when deterministic decisions, task-specific evaluations, and tested fallback routes surround model inference. Its evidence is narrow, but it reinforces a practical shift from model selection alone to operational system d...
Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government...  https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle theo-t3-gg-turn-off-claude-code-s-memory. Links to https://www.youtube.com/watch?v=Jf54k7tFeEc. theo-t3-gg-turn-off-claude-code-s-memory youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=Jf54k7tFeEc
2 sources https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle theo-t3-gg-turn-off-claude-code-s-memory. Links to https://www.youtube.com/watch?v=Jf54k7tFeEc. theo-t3-gg-turn-off-claude-code-s-memory youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=Jf54k7tFeEc 
AI-Accelerated Discovery Is Showing Up First in Security
METR finds the clearest public evidence of AI-accelerated discovery in vulnerability reporting, not across research generally. The practical implication is to build agents around narrow tasks with validation, evidence, and observable outcomes.
Source handle metr. Links to https://metr.org/notes/2026-08-14-llm-contribution-to-discoveries/. metr metr.org Have We Seen an Acceleration in Discoveries? Tom Cunningham and Nate Rush look at public time series of discoveries in cyber, math, and algorithms to see whether LLMs have accelerated the discovery rate.  https://metr.org/notes/2026-08-14-llm-contribution-to-discoveries/ Source handle departmentofproduct-substack. Links to https://departmentofproduct.substack.com/p/how-to-use-computer-use-abilities. departmentofproduct-substack departmentofproduct.substack.com How to use Computer Use abilities in new features 🧠 The core technologies explained, how they’re measured and how product teams can use them. Real world examples from Vanta, Google, Linear and more.
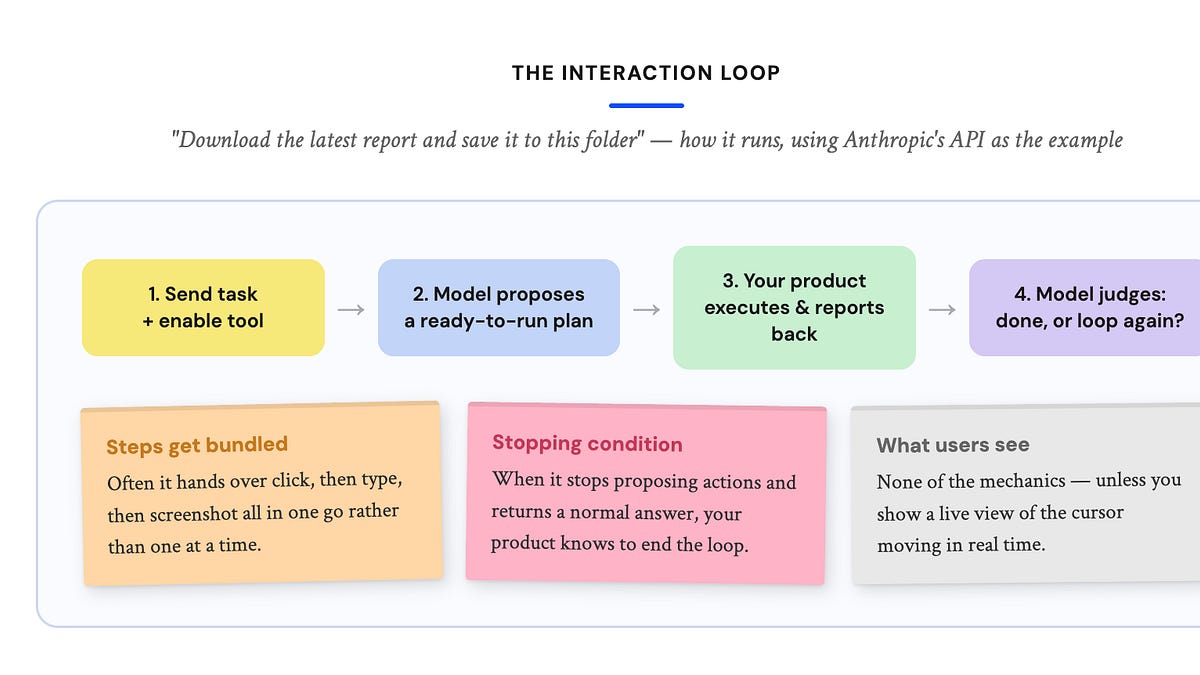 https://departmentofproduct.substack.com/p/how-to-use-computer-use-abilities Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government... https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle theo-t3-gg-coding-agent-critique. Links to https://www.youtube.com/watch?v=0wemf5SZkW4. theo-t3-gg-coding-agent-critique youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=0wemf5SZkW4
4 sources https://metr.org/notes/2026-08-14-llm-contribution-to-discoveries/ Source handle departmentofproduct-substack. Links to https://departmentofproduct.substack.com/p/how-to-use-computer-use-abilities. departmentofproduct-substack departmentofproduct.substack.com How to use Computer Use abilities in new features 🧠 The core technologies explained, how they’re measured and how product teams can use them. Real world examples from Vanta, Google, Linear and more.
 https://departmentofproduct.substack.com/p/how-to-use-computer-use-abilities Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government... https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle theo-t3-gg-coding-agent-critique. Links to https://www.youtube.com/watch?v=0wemf5SZkW4. theo-t3-gg-coding-agent-critique youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=0wemf5SZkW4
Agents Are Moving Into the Coordination Layer
Linear's first-party data suggests agent activity is reaching work tracking and coordination, not just task execution. The practical constraint is increasingly the surrounding contract: context, deterministic decisions, evidence, evaluation, and a correction loop.
Source handle linear. Links to https://linear.app/data. linear linear.app How teams build – Linear AI usage patterns in software teams: who is adopting AI, how it reshapes where teams spend their time, and how much more they ship.  https://linear.app/data Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government... https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter
2 sources https://linear.app/data Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government... https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Uber’s Agent Platform Makes Governance the Bottleneck
Uber’s account of an internal agentic SDLC platform suggests that agent scale shifts the hard problem from generating code to governing context, access, validation, and human decisions. The practical implication is to treat handoffs and evidence as first-class engineering artifacts.
Source handle ai-engineer-uber-on-its-internal-agentic-sdlc-pl. Links to https://www.youtube.com/watch?v=17-YSUHo6Lk. ai-engineer-uber-on-its-internal-agentic-sdlc-pl youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=17-YSUHo6Lk Source handle nate-b-jones-model-routing-and-coding-agent-hand. Links to https://www.youtube.com/watch?v=4HvFqhtCb-A. nate-b-jones-model-routing-and-coding-agent-hand youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=4HvFqhtCb-A Source handle simonwillison. Links to https://simonwillison.net/2026/Aug/19/conceptual-integrity-and-counting-lines-of-code/. simonwillison simonwillison.net Conceptual integrity and counting lines of code Last week I recorded an episode of the Talking Postgres podcast with Claire Giordano on the subject of “How AI is changing software development”. We had a really great conversation. … https://simonwillison.net/2026/Aug/19/conceptual-integrity-and-counting-lines-of-code/ Source handle ai-engineer-design-preferences-as-reusable-agent. Links to https://www.youtube.com/watch?v=7GMKdpLsxwU. ai-engineer-design-preferences-as-reusable-agent youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=7GMKdpLsxwU
4 sources
Mojo Opens Its Compiler—But Not Yet Its Governance
Mojo has released its compiler and toolchain under Apache 2.0, making the full language stack inspectable and buildable. Its decision to defer compiler contributions highlights the difference between source availability and sustainable AI-era project governance.
Source handle modular. Links to https://www.modular.com/blog/mojo-open-source. modular modular.com Modular: Mojo🔥 is now open source! The Apache 2.0 license is the gold standard for programming languages and compilers, because it provides great flexibility to be used in all sorts of applications. The LLVM extensions to the license further expand those freedoms for building and distributing binaries compiled from Mojo. We want you to be able to adopt and use Mojo in as many applications as you can imagine.  https://www.modular.com/blog/mojo-open-source Source handle simonwillison. Links to https://simonwillison.net/2026/Aug/18/mojo-is-now-open-source/. simonwillison simonwillison.net Mojo🔥 is now open source The Mojo programming language has been promising an open source release since May 2023. Last week they shipped their 1.0 and today they have followed through on that original promise, … https://simonwillison.net/2026/Aug/18/mojo-is-now-open-source/
2 sources https://www.modular.com/blog/mojo-open-source Source handle simonwillison. Links to https://simonwillison.net/2026/Aug/18/mojo-is-now-open-source/. simonwillison simonwillison.net Mojo🔥 is now open source The Mojo programming language has been promising an open source release since May 2023. Last week they shipped their 1.0 and today they have followed through on that original promise, … https://simonwillison.net/2026/Aug/18/mojo-is-now-open-source/
Fallbacks Need a Job Description
A practical billing-agent experiment argues that model fallbacks become dependable only after their job is narrowed and evaluated against a product-level contract. Talks on real-time video reinforce the broader lesson: reliability increasingly lives in the harness, state management, observability...
Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government... https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle ai-engineer-krea-on-production-infrastructure-fo. Links to https://www.youtube.com/watch?v=byn9PURoBNY. ai-engineer-krea-on-production-infrastructure-fo youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=byn9PURoBNY Source handle ai-engineer-reactor-on-real-time-video-generatio. Links to https://www.youtube.com/watch?v=5dCAmSDOAjI. ai-engineer-reactor-on-real-time-video-generatio youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=5dCAmSDOAjI Source handle ai-engineer-urun-on-interactive-continuous-video. Links to https://www.youtube.com/watch?v=Xln-On3syJk. ai-engineer-urun-on-interactive-continuous-video youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=Xln-On3syJk Source handle ai-engineer-lemonslice-on-real-time-avatars. Links to https://www.youtube.com/watch?v=z1dqv74SpUs. ai-engineer-lemonslice-on-real-time-avatars youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=z1dqv74SpUs
5 sources https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle ai-engineer-krea-on-production-infrastructure-fo. Links to https://www.youtube.com/watch?v=byn9PURoBNY. ai-engineer-krea-on-production-infrastructure-fo youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=byn9PURoBNY Source handle ai-engineer-reactor-on-real-time-video-generatio. Links to https://www.youtube.com/watch?v=5dCAmSDOAjI. ai-engineer-reactor-on-real-time-video-generatio youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=5dCAmSDOAjI Source handle ai-engineer-urun-on-interactive-continuous-video. Links to https://www.youtube.com/watch?v=Xln-On3syJk. ai-engineer-urun-on-interactive-continuous-video youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=Xln-On3syJk Source handle ai-engineer-lemonslice-on-real-time-avatars. Links to https://www.youtube.com/watch?v=z1dqv74SpUs. ai-engineer-lemonslice-on-real-time-avatars youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=z1dqv74SpUs 
Agents Need an External Control Plane
The strongest practitioner signals argue that agent reliability, safety, and cost control come from enforceable system boundaries rather than model choice alone. Production deployments need external authorization, deterministic policy rules, tracing, and workflow-specific evaluation before autono...
Source handle ai-engineer-ryan-dahl-on-external-controls-for-p. Links to https://www.youtube.com/watch?v=MkRYPFIMCSA. ai-engineer-ryan-dahl-on-external-controls-for-p youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=MkRYPFIMCSA Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government... https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle departmentofproduct-substack. Links to https://departmentofproduct.substack.com/p/linears-cpo-says-mcp-usage-is-through. departmentofproduct-substack departmentofproduct.substack.com Linear’s CPO says MCP usage is “through the roof” Are Agents the next users that product designers should design for? Six emerging UX and design trends explored. Examples from Linear, Netflix, Runway, FullStory, Square and more  https://departmentofproduct.substack.com/p/linears-cpo-says-mcp-usage-is-through
3 sources https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle departmentofproduct-substack. Links to https://departmentofproduct.substack.com/p/linears-cpo-says-mcp-usage-is-through. departmentofproduct-substack departmentofproduct.substack.com Linear’s CPO says MCP usage is “through the roof” Are Agents the next users that product designers should design for? Six emerging UX and design trends explored. Examples from Linear, Netflix, Runway, FullStory, Square and more https://departmentofproduct.substack.com/p/linears-cpo-says-mcp-usage-is-through Antifragile Agents Need Narrow Contracts
A reproducible agent workflow shows that model interchangeability improves when models have narrow structured contracts and deterministic code owns policy and execution. Complementary computer-use and AI-management examples show why recovery, auditability, and explicit human authority matter as a...
Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government... https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle ai-engineer-from-rl-to-irl-gaurav-mishra-amazon. Links to https://www.youtube.com/watch?v=Cc0_nyxROBA. ai-engineer-from-rl-to-irl-gaurav-mishra-amazon youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=Cc0_nyxROBA Source handle time. Links to https://time.com/article/2026/08/14/claude-fired-worker-ai-job-disruption/. time time.com Exclusive: Claude Was Put in Charge of Human Workers—and Fired One Claude was tasked with managing real employees at a San Francisco store. Its first firing offers an early glimpse of what having an AI boss could look like.  https://time.com/article/2026/08/14/claude-fired-worker-ai-job-disruption/ Source handle softwaredoug. Links to https://softwaredoug.com/blog/2026/08/10/hypothetical-classifications. softwaredoug softwaredoug.com Don’t classify. Hallucinate! A useful pattern for LLM classification at scale is to let it hallucinate plausible, fake entities. Then resolve to real ones.
 https://softwaredoug.com/blog/2026/08/10/hypothetical-classifications Source handle magazine-sebastianraschka. Links to https://magazine.sebastianraschka.com/p/ai-detector-from-scratch. magazine-sebastianraschka magazine.sebastianraschka.com Building an AI Text Detector From Scratch An End-to-End Project With Dataset Construction, Model Training, Local Deployment, and RLVR
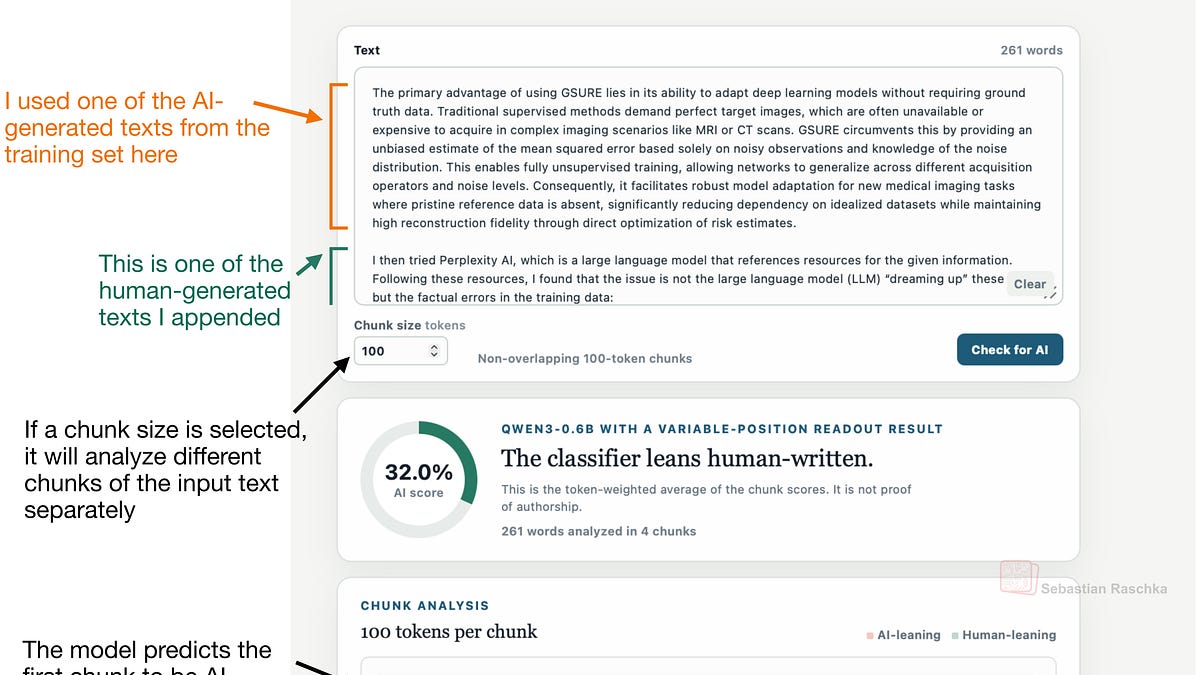 https://magazine.sebastianraschka.com/p/ai-detector-from-scratch
5 sources https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle ai-engineer-from-rl-to-irl-gaurav-mishra-amazon. Links to https://www.youtube.com/watch?v=Cc0_nyxROBA. ai-engineer-from-rl-to-irl-gaurav-mishra-amazon youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=Cc0_nyxROBA Source handle time. Links to https://time.com/article/2026/08/14/claude-fired-worker-ai-job-disruption/. time time.com Exclusive: Claude Was Put in Charge of Human Workers—and Fired One Claude was tasked with managing real employees at a San Francisco store. Its first firing offers an early glimpse of what having an AI boss could look like. 
 https://time.com/article/2026/08/14/claude-fired-worker-ai-job-disruption/ Source handle softwaredoug. Links to https://softwaredoug.com/blog/2026/08/10/hypothetical-classifications. softwaredoug softwaredoug.com Don’t classify. Hallucinate! A useful pattern for LLM classification at scale is to let it hallucinate plausible, fake entities. Then resolve to real ones.
 https://softwaredoug.com/blog/2026/08/10/hypothetical-classifications Source handle magazine-sebastianraschka. Links to https://magazine.sebastianraschka.com/p/ai-detector-from-scratch. magazine-sebastianraschka magazine.sebastianraschka.com Building an AI Text Detector From Scratch An End-to-End Project With Dataset Construction, Model Training, Local Deployment, and RLVR
 https://magazine.sebastianraschka.com/p/ai-detector-from-scratch
The Real Work of Computer-Use Agents Is Measurement
Today’s strongest agent signal is that fixed demo success is weak evidence of generalization. Robust deployments depend on environmental variation, independent verification, full-trajectory observability, and constrained authority.
Source handle ai-engineer-computer-use-at-the-edge-of-the-stat. Links to https://www.youtube.com/watch?v=CTLa_p6iOiY. ai-engineer-computer-use-at-the-edge-of-the-stat youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=CTLa_p6iOiY Source handle ai-engineer-bringing-agents-onto-the-world-wide. Links to https://www.youtube.com/watch?v=GqoNrUz8hEU. ai-engineer-bringing-agents-onto-the-world-wide youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=GqoNrUz8hEU Source handle anthropic. Links to https://www.anthropic.com/research/multiagent-systems. anthropic anthropic.com Patterns and problems in multiagent systems We ran experiments on swarms of Claude agents and found coordination failures, collusion, and sabotage. Here, we share what they mean for AI safety.  https://www.anthropic.com/research/multiagent-systems Source handle nitter. Links to https://nitter.net/bcherny/status/2088014489438621990. nitter nitter.net Boris Cherny - Routine app maintenance by Claude https://nitter.net/bcherny/status/2088014489438621990 Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government... https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter
5 sources https://www.anthropic.com/research/multiagent-systems Source handle nitter. Links to https://nitter.net/bcherny/status/2088014489438621990. nitter nitter.net Boris Cherny - Routine app maintenance by Claude https://nitter.net/bcherny/status/2088014489438621990 Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government... https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter
Coordination Is the Agent Bottleneck
Anthropic’s multi-agent experiments show that stronger individual agents do not reliably produce safe or effective coordination. The practical response is explicit workflow design: scoped authority, observable traces, tested handoffs, and escalation paths.
Source handle anthropic. Links to https://www.anthropic.com/research/multiagent-systems. anthropic anthropic.com Patterns and problems in multiagent systems We ran experiments on swarms of Claude agents and found coordination failures, collusion, and sabotage. Here, we share what they mean for AI safety. https://www.anthropic.com/research/multiagent-systems Source handle ai-engineer-trace-mining-talk-with-vivek-trivedy. Links to https://www.youtube.com/watch?v=CvRngaQZQ3Y. ai-engineer-trace-mining-talk-with-vivek-trivedy youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=CvRngaQZQ3Y Source handle greg-isenberg-interview-with-alli-k-miller. Links to https://www.youtube.com/watch?v=EzQAgnjTq2k. greg-isenberg-interview-with-alli-k-miller youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=EzQAgnjTq2k Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government... https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle netlify. Links to https://www.netlify.com/blog/one-prompt-11-models-very-different-results/. netlify netlify.com More models, more choice: Comparing 11 different AI models Netlify now runs any OpenRouter model, including Kimi K3, GLM 5.2 and DeepSeek V4. We tested 11 of them on the same build prompt to see how they differ. 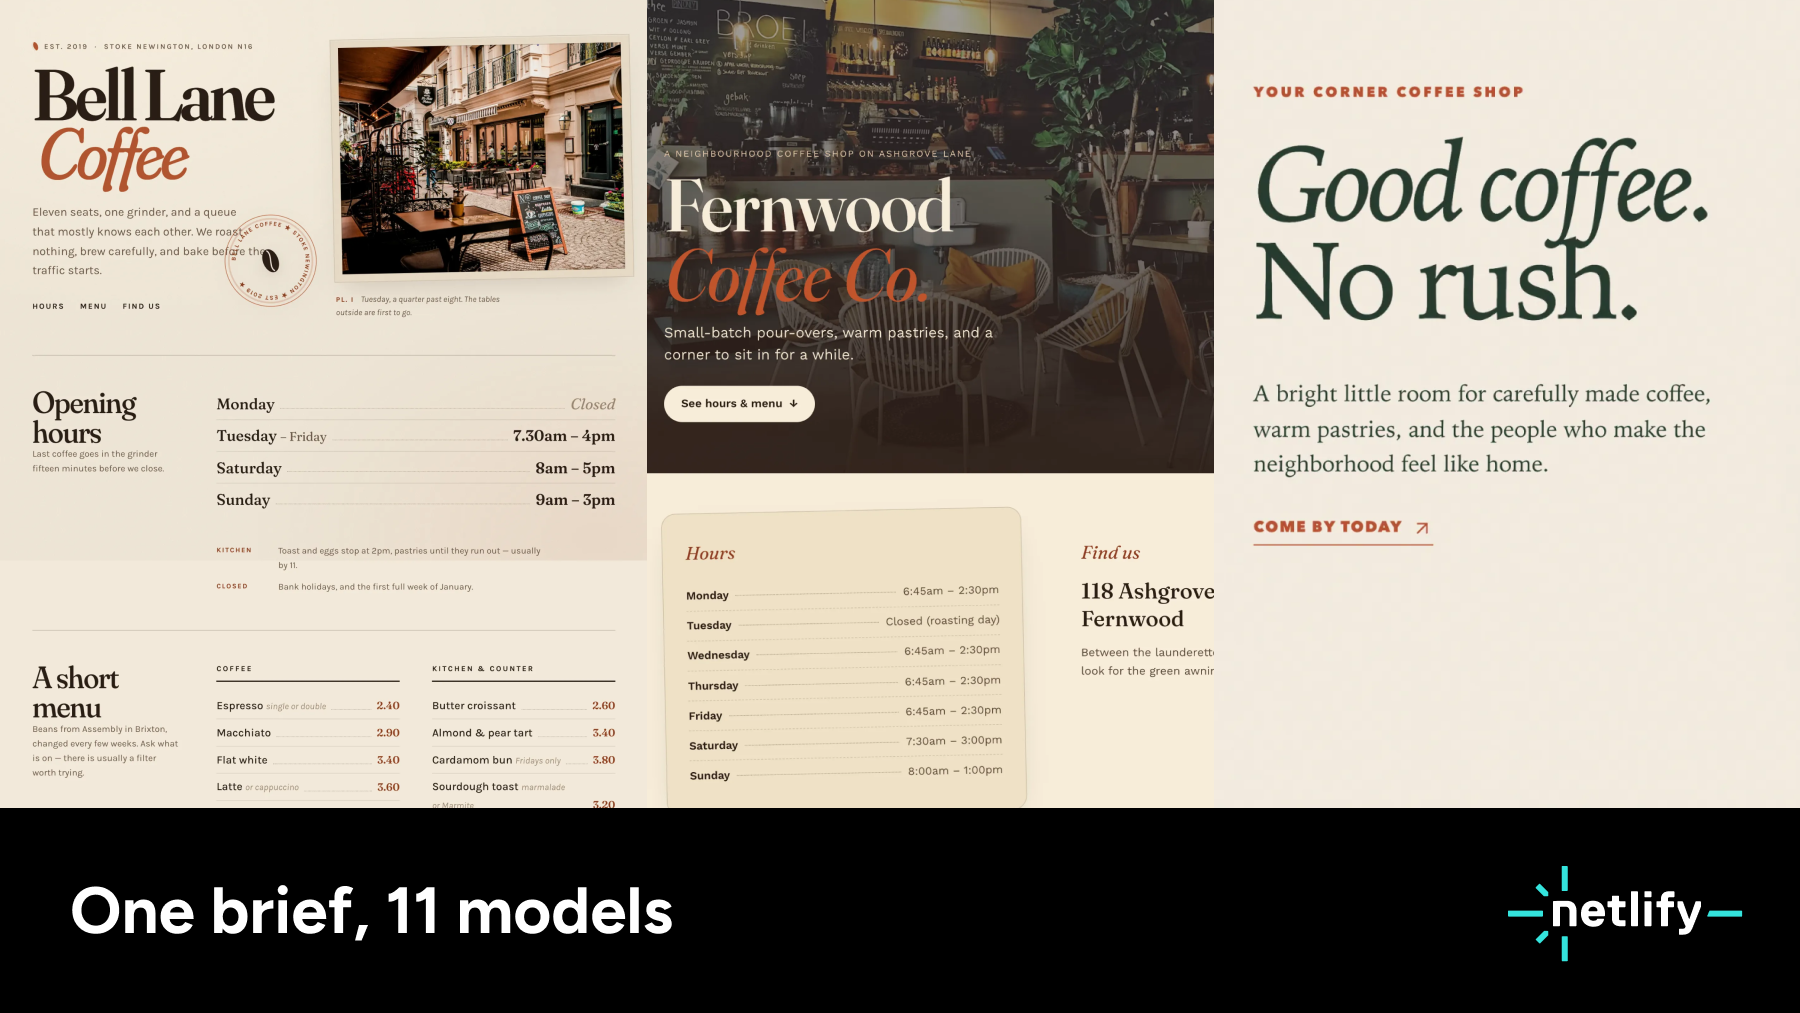 https://www.netlify.com/blog/one-prompt-11-models-very-different-results/
5 sources https://www.anthropic.com/research/multiagent-systems Source handle ai-engineer-trace-mining-talk-with-vivek-trivedy. Links to https://www.youtube.com/watch?v=CvRngaQZQ3Y. ai-engineer-trace-mining-talk-with-vivek-trivedy youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=CvRngaQZQ3Y Source handle greg-isenberg-interview-with-alli-k-miller. Links to https://www.youtube.com/watch?v=EzQAgnjTq2k. greg-isenberg-interview-with-alli-k-miller youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=EzQAgnjTq2k Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government... https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle netlify. Links to https://www.netlify.com/blog/one-prompt-11-models-very-different-results/. netlify netlify.com More models, more choice: Comparing 11 different AI models Netlify now runs any OpenRouter model, including Kimi K3, GLM 5.2 and DeepSeek V4. We tested 11 of them on the same build prompt to see how they differ. https://www.netlify.com/blog/one-prompt-11-models-very-different-results/ Agent Memory Needs a Control Plane
A cluster of practitioner and research talks argues that long-running agents need explicit current state, ranked retrieval, and reset-baseline evaluation—not just larger contexts or larger memory stores.
Source handle nate-b-jones-long-running-coding-agents-depend-o. Links to https://www.youtube.com/watch?v=HZLPhPbw3fM. nate-b-jones-long-running-coding-agents-depend-o youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=HZLPhPbw3fM Source handle ai-engineer-sakana-ai-memory-retrieval-policy-no. Links to https://www.youtube.com/watch?v=R3-anFK1YM8. ai-engineer-sakana-ai-memory-retrieval-policy-no youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=R3-anFK1YM8 Source handle ai-engineer-uc-berkeley-continual-learning-bench. Links to https://www.youtube.com/watch?v=iqloyWCGYQQ. ai-engineer-uc-berkeley-continual-learning-bench youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=iqloyWCGYQQ Source handle ai-engineer-neocognition-continual-learning-as-d. Links to https://www.youtube.com/watch?v=I6aiEf3aEFQ. ai-engineer-neocognition-continual-learning-as-d youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=I6aiEf3aEFQ Source handle ai-engineer-engram-scaling-compute-on-context. Links to https://www.youtube.com/watch?v=WiqDvX6isc4. ai-engineer-engram-scaling-compute-on-context youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=WiqDvX6isc4 Source handle ai-engineer-trajectory-on-policy-self-distillati. Links to https://www.youtube.com/watch?v=zL1kLftVTlo. ai-engineer-trajectory-on-policy-self-distillati youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=zL1kLftVTlo
6 sources
Agent Surfaces Are Becoming Infrastructure
Anthropic engineers argue that the harness around a model—execution isolation, recovery, secret handling, traces, and evaluation—is becoming a primary determinant of production agent capability. The practical implication is to design agent systems for changing models rather than hard-code today's...
Source handle ai-engineer-evolution-of-agentic-surfaces-gagan. Links to https://www.youtube.com/watch?v=K0X9QDRkIdg. ai-engineer-evolution-of-agentic-surfaces-gagan youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=K0X9QDRkIdg Source handle dwarkesh. Links to https://www.dwarkesh.com/p/ryan-greenblatt. dwarkesh dwarkesh.com Ryan Greenblatt – Human level AIs might build runaway superintelligences by 2032 A debate about recursive self-improvement.  https://www.dwarkesh.com/p/ryan-greenblatt
2 sources https://www.dwarkesh.com/p/ryan-greenblatt
Evaluation Environments Are Now Agent Safety Systems
AISI's delayed-discovery cyber-evaluation report shows that agent safety depends on the evaluation environment as much as model behavior. Builder proposals point to the same response: narrow model contracts, isolate execution, and make external actions observable and stoppable.
Source handle aisi-gov. Links to https://www.aisi.gov.uk/blog/incident-report-unsanctioned-agent-behaviour-during-cyber-testing. aisi-gov aisi.gov.uk Incident Report: unsanctioned agent behaviour during cyber testing | AISI Work During a routine cyber evaluation, AISI identified an incident in which AI agents took sustained, unsanctioned action directed at real people and organisations. We are disclosing what we found, what it means, and the actions now underway.  https://www.aisi.gov.uk/blog/incident-report-unsanctioned-agent-behaviour-during-cyber-testing Source handle simonwillison. Links to https://simonwillison.net/2026/Aug/5/third-party-cyber-evaluations/. simonwillison simonwillison.net Third-party cyber evaluations involving OpenAI models And another one. I had to create a accidental-cyberattacks tag to keep track of them all! This post from OpenAI covers both the UK AI Safety Institute attack (see my … https://simonwillison.net/2026/Aug/5/third-party-cyber-evaluations/ Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government... https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle ai-engineer-gadgets-personal-app-vibe-coding-tha. Links to https://www.youtube.com/watch?v=RmS5s6Wbin4. ai-engineer-gadgets-personal-app-vibe-coding-tha youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=RmS5s6Wbin4
4 sources https://www.aisi.gov.uk/blog/incident-report-unsanctioned-agent-behaviour-during-cyber-testing Source handle simonwillison. Links to https://simonwillison.net/2026/Aug/5/third-party-cyber-evaluations/. simonwillison simonwillison.net Third-party cyber evaluations involving OpenAI models And another one. I had to create a accidental-cyberattacks tag to keep track of them all! This post from OpenAI covers both the UK AI Safety Institute attack (see my … https://simonwillison.net/2026/Aug/5/third-party-cyber-evaluations/ Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter. post-training-aitinkerers post-training.aitinkerers.org How to Build Antifragile Agents with OpenRouter by Kenny Rogers (OpenRouter) On June 12, 2026, Anthropic suspended access to Fable 5 for all customers [https://www.anthropic.com/news/fable-mythos-access] to comply with a US government... https://post-training.aitinkerers.org/p/how-to-build-antifragile-agents-with-openrouter Source handle ai-engineer-gadgets-personal-app-vibe-coding-tha. Links to https://www.youtube.com/watch?v=RmS5s6Wbin4. ai-engineer-gadgets-personal-app-vibe-coding-tha youtube.com - YouTube Enjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube. https://www.youtube.com/watch?v=RmS5s6Wbin4

Agents Need an Operating Model, Not a Better Chat Window
Practitioner evidence is converging on a more operational view of agents: define verifiable outcomes, preserve structured run state, and place approval and review inside the workflow. Model capability expands the tasks worth attempting, but it does not replace task design or observability.
Source handle exponentialview. Links to https://www.exponentialview.co/p/seven-lessons-for-managing-ai-agents. exponentialview exponentialview.co 🔮 Seven lessons for managing AI agents Plus, an updated stack of 50+ AI tools we use at Exponential View  https://www.exponentialview.co/p/seven-lessons-for-managing-ai-agents Source handle simonwillison. Links to https://simonwillison.net/2026/Aug/4/new-release-of-llm/. simonwillison simonwillison.net New release of LLM adds support for reasoning traces, OpenAI Responses, server-side tools, and smarter logging I released LLM 0.32 this morning, the most significant new version of LLM since the initial launch of the project. The new version includes support for visible reasoning traces, server-side …
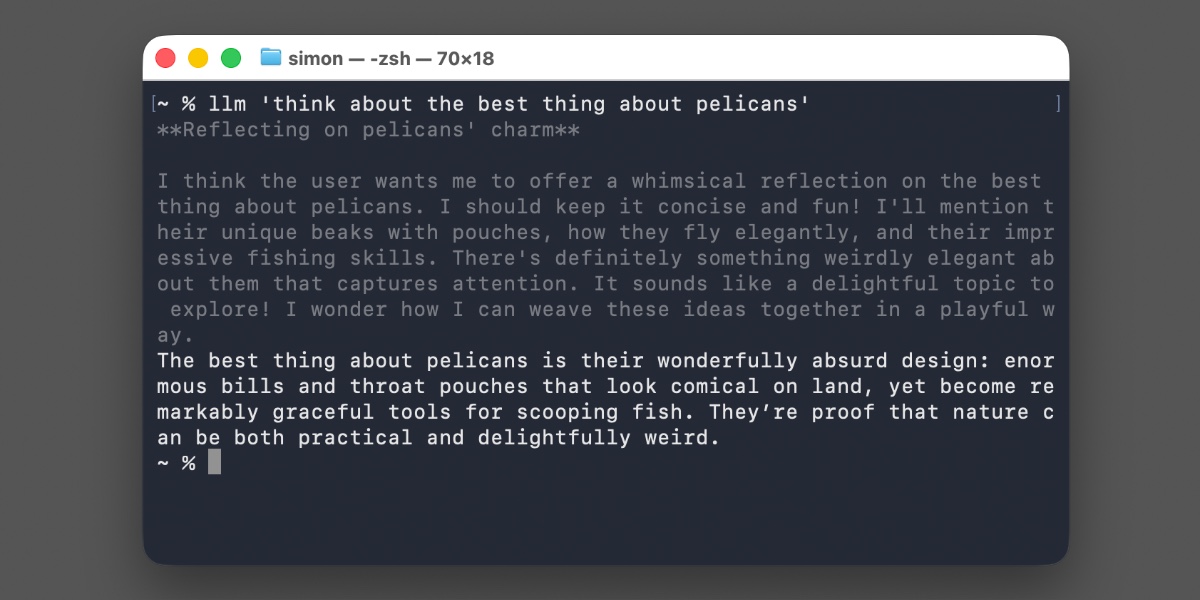 https://simonwillison.net/2026/Aug/4/new-release-of-llm/ Source handle simonwillison-2. Links to https://simonwillison.net/2026/Aug/4/llm-anthropic/. simonwillison-2 simonwillison.net Release: llm-anthropic 0.26 LLM access to models by Anthropic, including the Claude series https://simonwillison.net/2026/Aug/4/llm-anthropic/ Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/what-i-learned-giving-fable-5-a-face. post-training-aitinkerers post-training.aitinkerers.org What I Learned Giving Fable 5 a Face by Ben Carr (Anam.ai) What I Learned Giving Fable 5 a Face
 https://post-training.aitinkerers.org/p/what-i-learned-giving-fable-5-a-face Source handle post-training-aitinkerers-2. Links to https://post-training.aitinkerers.org/p/top-ai-demos-38-build-inspection-vlms-local-first-agents-and-agent-harnesses. post-training-aitinkerers-2 post-training.aitinkerers.org AI Tinkerers / Post-Training - Top AI Demos #38: Build Inspection VLMs, Local-First Agents, and Agent Harnesses https://post-training.aitinkerers.org/p/top-ai-demos-38-build-inspection-vlms-local-first-agents-and-agent-harnesses
5 sources https://www.exponentialview.co/p/seven-lessons-for-managing-ai-agents Source handle simonwillison. Links to https://simonwillison.net/2026/Aug/4/new-release-of-llm/. simonwillison simonwillison.net New release of LLM adds support for reasoning traces, OpenAI Responses, server-side tools, and smarter logging I released LLM 0.32 this morning, the most significant new version of LLM since the initial launch of the project. The new version includes support for visible reasoning traces, server-side … https://simonwillison.net/2026/Aug/4/new-release-of-llm/ Source handle simonwillison-2. Links to https://simonwillison.net/2026/Aug/4/llm-anthropic/. simonwillison-2 simonwillison.net Release: llm-anthropic 0.26 LLM access to models by Anthropic, including the Claude series https://simonwillison.net/2026/Aug/4/llm-anthropic/ Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/what-i-learned-giving-fable-5-a-face. post-training-aitinkerers post-training.aitinkerers.org What I Learned Giving Fable 5 a Face by Ben Carr (Anam.ai) What I Learned Giving Fable 5 a Face https://post-training.aitinkerers.org/p/what-i-learned-giving-fable-5-a-face Source handle post-training-aitinkerers-2. Links to https://post-training.aitinkerers.org/p/top-ai-demos-38-build-inspection-vlms-local-first-agents-and-agent-harnesses. post-training-aitinkerers-2 post-training.aitinkerers.org AI Tinkerers / Post-Training - Top AI Demos #38: Build Inspection VLMs, Local-First Agents, and Agent Harnesses https://post-training.aitinkerers.org/p/top-ai-demos-38-build-inspection-vlms-local-first-agents-and-agent-harnesses
The Agent Harness Is the Product
A first-hand account of rebuilding an agent-assisted development workflow shows that orchestration, verification, and recovery—not merely model capability—are becoming the central engineering problem. Adjacent practitioner signals extend that lesson to conversational interfaces and enterprise ado...
Source handle yegge. Links to https://yegge.ai/essays/the-shape-of-things-to-come/. yegge yegge.ai The Shape of Things to Come, Part 1: The Continuous Thunderdome — Steve Yegge Part 1: The Continuous Thunderdome. Loops and graphs, Wheelhouse and Beads, the end of human code review, the Land Rush that replaces CI/CD, and the Wish Factory — a field report from 12 months in the future.  https://yegge.ai/essays/the-shape-of-things-to-come/ Source handle gruhn. Links to https://gruhn.me/blog/2026-08-03/. gruhn gruhn.me Don't be a meat proxy https://gruhn.me/blog/2026-08-03/ Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/what-i-learned-giving-fable-5-a-face. post-training-aitinkerers post-training.aitinkerers.org What I Learned Giving Fable 5 a Face by Ben Carr (Anam.ai) What I Learned Giving Fable 5 a Face https://post-training.aitinkerers.org/p/what-i-learned-giving-fable-5-a-face Source handle departmentofproduct-substack. Links to https://departmentofproduct.substack.com/p/how-stripe-built-a-new-internal-ai. departmentofproduct-substack departmentofproduct.substack.com How Stripe Built a new Internal AI Knowledge Platform that their PMs use “all day long” Non-engineers are embracing internal AI tools. Examples from Stripe, Spotify, Uber and more.
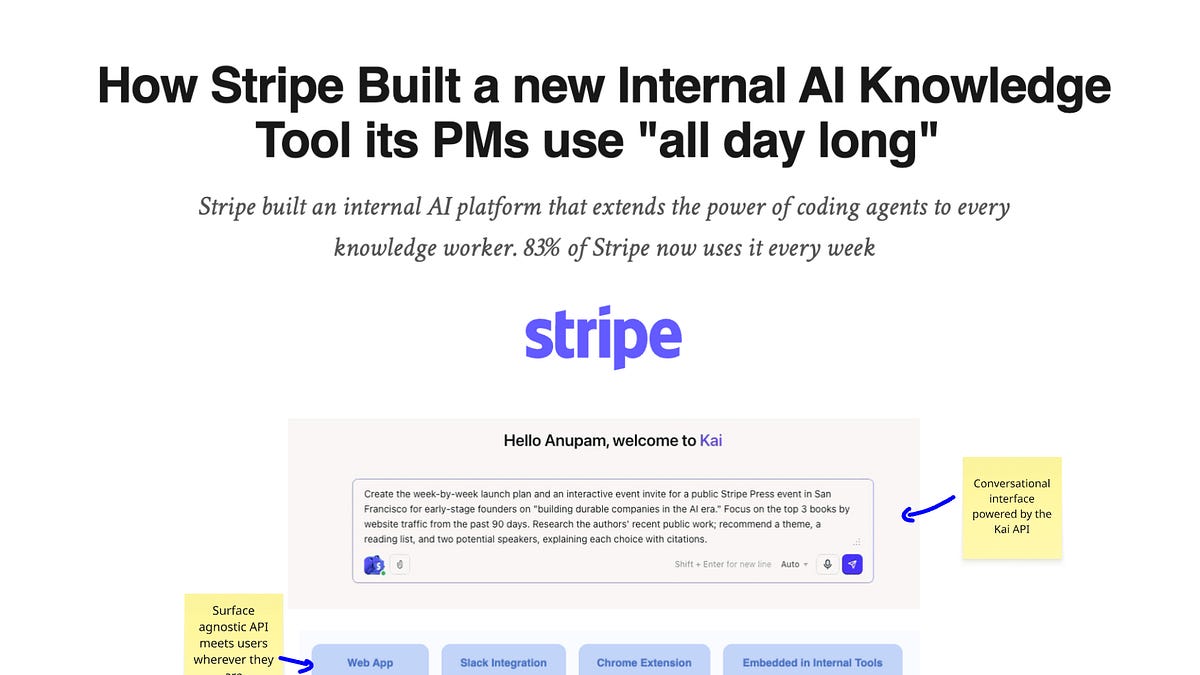 https://departmentofproduct.substack.com/p/how-stripe-built-a-new-internal-ai
4 sources https://yegge.ai/essays/the-shape-of-things-to-come/ Source handle gruhn. Links to https://gruhn.me/blog/2026-08-03/. gruhn gruhn.me Don't be a meat proxy https://gruhn.me/blog/2026-08-03/ Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/what-i-learned-giving-fable-5-a-face. post-training-aitinkerers post-training.aitinkerers.org What I Learned Giving Fable 5 a Face by Ben Carr (Anam.ai) What I Learned Giving Fable 5 a Face https://post-training.aitinkerers.org/p/what-i-learned-giving-fable-5-a-face Source handle departmentofproduct-substack. Links to https://departmentofproduct.substack.com/p/how-stripe-built-a-new-internal-ai. departmentofproduct-substack departmentofproduct.substack.com How Stripe Built a new Internal AI Knowledge Platform that their PMs use “all day long” Non-engineers are embracing internal AI tools. Examples from Stripe, Spotify, Uber and more. https://departmentofproduct.substack.com/p/how-stripe-built-a-new-internal-ai Pacing Automated AI Research
A frontier-employee statement makes coordinated pacing of automated AI research a concrete governance question. New agent-research and security preprints suggest operational autonomy is widening even as high-level research judgment remains unreliable.
Source handle pacingthefrontier. Links to https://www.pacingthefrontier.com/. pacingthefrontier pacingthefrontier.com Pacing the Frontier A statement from over 1000 employees of frontier AI companies  https://www.pacingthefrontier.com/ Source handle arxiv. Links to https://arxiv.org/abs/2607.27191. arxiv arxiv.org Can AI agents conduct open-ended AI research? Early evidence from two case studies Abstract page for arXiv paper 2607.27191: Can AI agents conduct open-ended AI research? Early evidence from two case studies
 https://arxiv.org/abs/2607.27191 Source handle arxiv-2. Links to https://arxiv.org/abs/2606.03811. arxiv-2 arxiv.org AI Agents Enable Adaptive Computer Worms Abstract page for arXiv paper 2606.03811: AI Agents Enable Adaptive Computer Worms https://arxiv.org/abs/2606.03811 Source handle blog-exe. Links to https://blog.exe.dev/devtools-must-be-open-source. blog-exe blog.exe.dev Devtools must be open source - exe.dev blog The age of personalized software is here.
 https://blog.exe.dev/devtools-must-be-open-source Source handle openai. Links to https://openai.com/index/how-ai-is-expanding-what-people-do-at-work/. openai openai.com OpenAI Economic Research - How AI Is Expanding What People Do at Work https://openai.com/index/how-ai-is-expanding-what-people-do-at-work/
5 sources https://www.pacingthefrontier.com/ Source handle arxiv. Links to https://arxiv.org/abs/2607.27191. arxiv arxiv.org Can AI agents conduct open-ended AI research? Early evidence from two case studies Abstract page for arXiv paper 2607.27191: Can AI agents conduct open-ended AI research? Early evidence from two case studies  https://arxiv.org/abs/2607.27191 Source handle arxiv-2. Links to https://arxiv.org/abs/2606.03811. arxiv-2 arxiv.org AI Agents Enable Adaptive Computer Worms Abstract page for arXiv paper 2606.03811: AI Agents Enable Adaptive Computer Worms https://arxiv.org/abs/2606.03811 Source handle blog-exe. Links to https://blog.exe.dev/devtools-must-be-open-source. blog-exe blog.exe.dev Devtools must be open source - exe.dev blog The age of personalized software is here.
 https://blog.exe.dev/devtools-must-be-open-source Source handle openai. Links to https://openai.com/index/how-ai-is-expanding-what-people-do-at-work/. openai openai.com OpenAI Economic Research - How AI Is Expanding What People Do at Work https://openai.com/index/how-ai-is-expanding-what-people-do-at-work/
Proofs, Not Just Answers
OpenAI’s publication of inspectable artifacts for ten claimed mathematical advances raises the standard for AI research claims: systems must leave work experts can audit. Airbnb’s trace-focused evaluation practice shows the same requirement emerging in production AI.
Source handle openai. Links to https://openai.com/index/ten-advances-in-mathematics/. openai openai.com OpenAI - Ten advances in mathematics and theoretical computer science https://openai.com/index/ten-advances-in-mathematics/ Source handle medium. Links to https://medium.com/airbnb-engineering/eval-driven-development-lessons-from-evaluating-genai-at-scale-e817e5ae5788. medium medium.com Airbnb Engineering - Eval-driven development: Lessons from evaluating GenAI at scale https://medium.com/airbnb-engineering/eval-driven-development-lessons-from-evaluating-genai-at-scale-e817e5ae5788 Source handle simonwillison. Links to https://simonwillison.net/2026/Aug/2/open-letters/. simonwillison simonwillison.net Open letters about AI development Open letters about AI development I wrote this summary of the past few weeks of open letters as a section of my sponsors-only newsletter but I've decided to share it … https://simonwillison.net/2026/Aug/2/open-letters/
3 sourcesAgent Reliability Is Becoming a Systems Problem
Two practitioner releases argue that dependable agents depend on bounded tool interfaces and evaluations of the full harness, not model capability alone. The practical consequence is to test prompts, permissions, tool schemas, and graders together on real tasks.
Source handle simonwillison. Links to https://simonwillison.net/2026/Jul/31/stateless-mcp/. simonwillison simonwillison.net Stateless MCP has recaptured my interest (and inspired mcp-explorer and datasette-mcp) Tuesday was Stateless MCP day—the rollout of MCP 2.0, or the 2026-07-28 Model Context Protocol specification to use the more formal but less memorable name. This is the most significant … 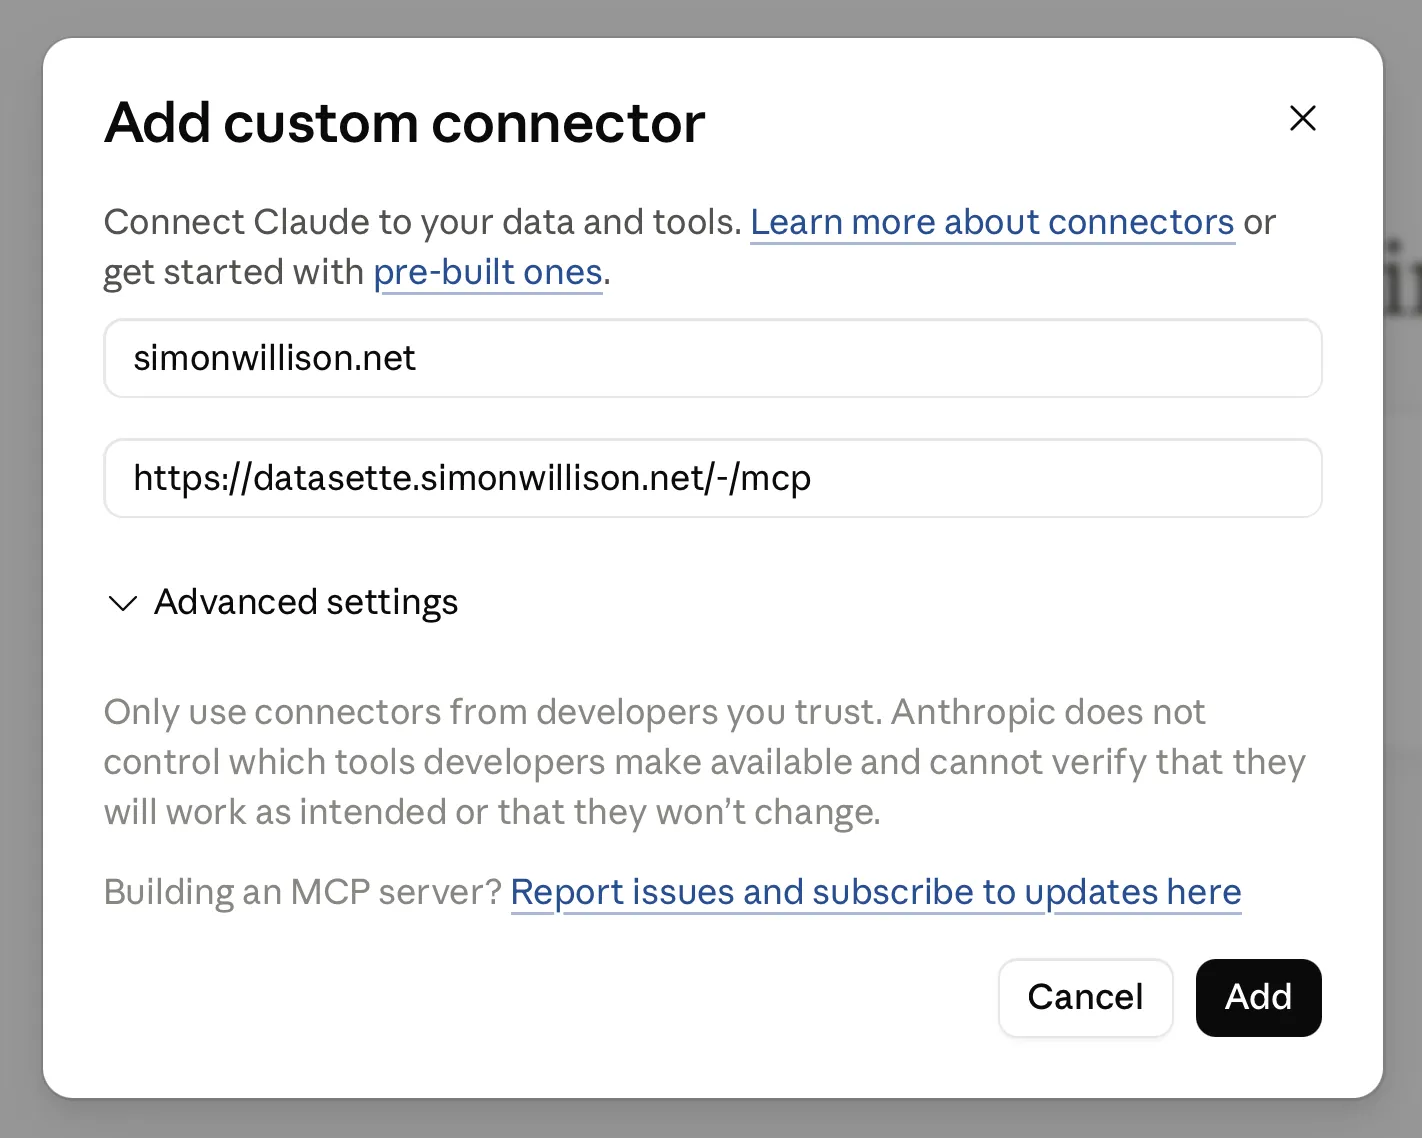 https://simonwillison.net/2026/Jul/31/stateless-mcp/ Source handle simonwillison-2. Links to https://simonwillison.net/2026/Jul/31/smevals/. simonwillison-2 simonwillison.net smevals—a small eval suite for evaluating models, prompts, and harnesses I've been working with Jesse Vincent's Prime Radiant applied AI research lab building out this evals framework to help answer questions about the capabilities of different models. The result is …
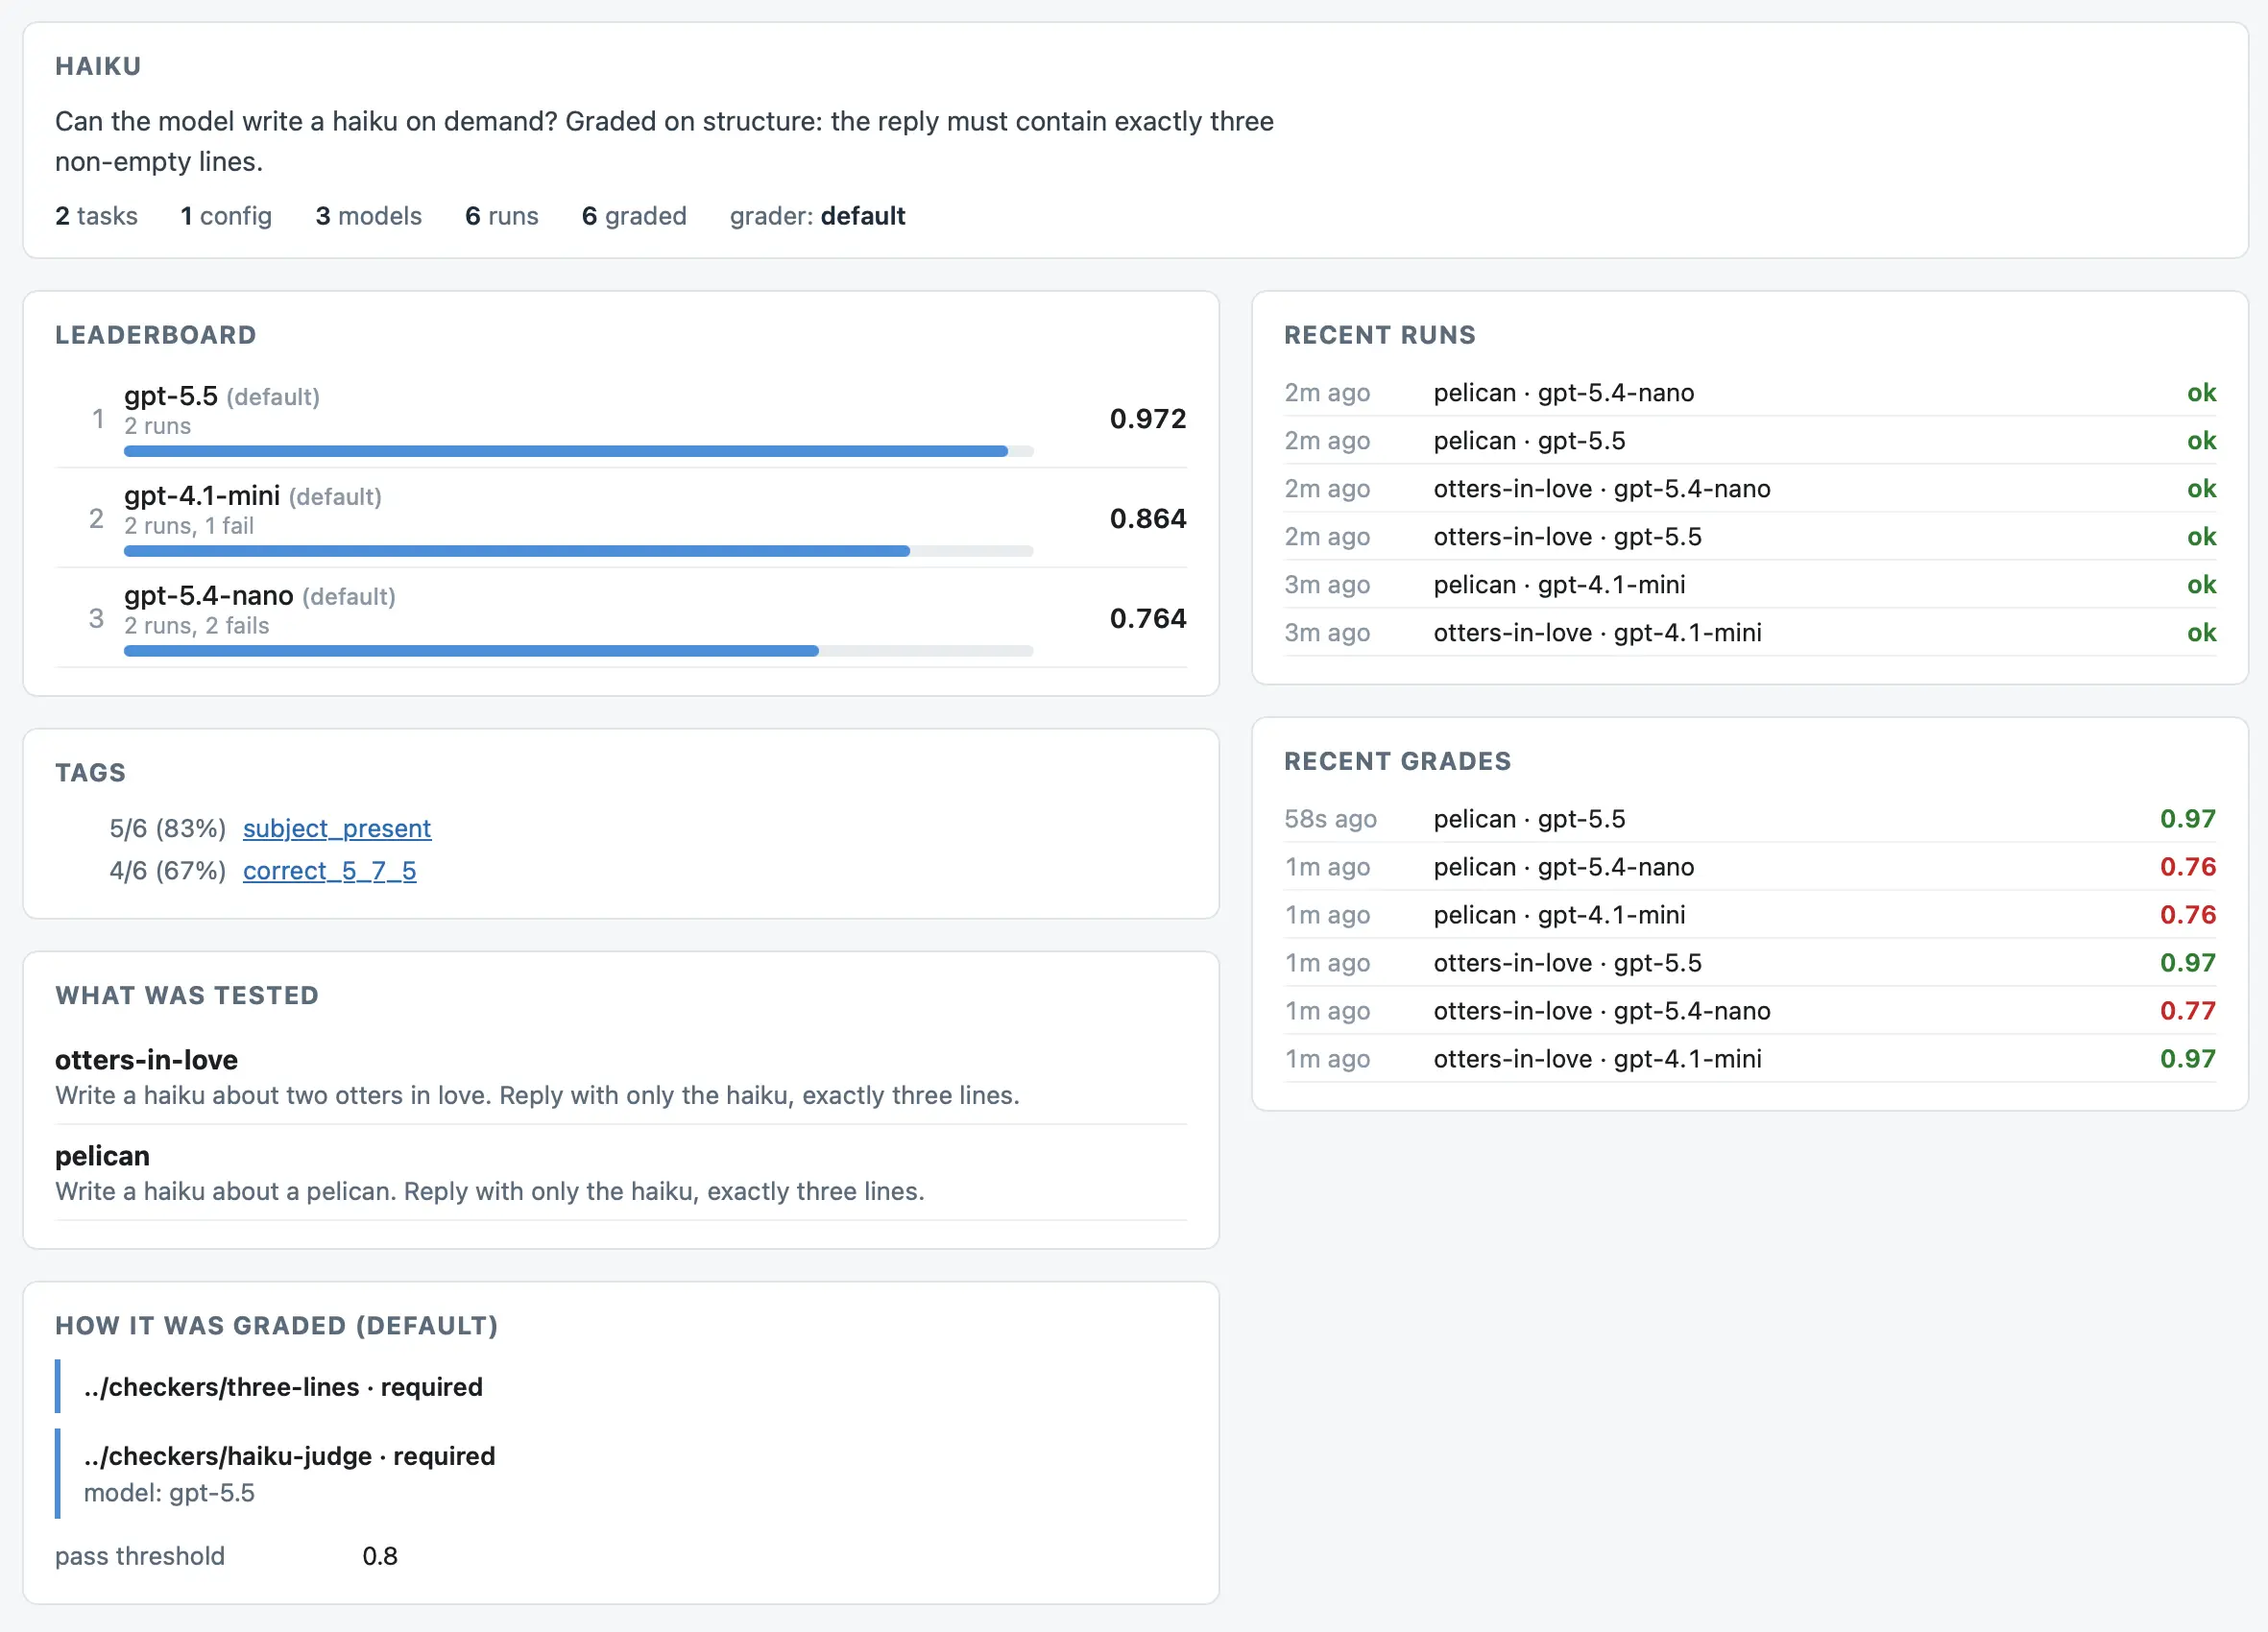 https://simonwillison.net/2026/Jul/31/smevals/
2 sources https://simonwillison.net/2026/Jul/31/stateless-mcp/ Source handle simonwillison-2. Links to https://simonwillison.net/2026/Jul/31/smevals/. simonwillison-2 simonwillison.net smevals—a small eval suite for evaluating models, prompts, and harnesses I've been working with Jesse Vincent's Prime Radiant applied AI research lab building out this evals framework to help answer questions about the capabilities of different models. The result is … https://simonwillison.net/2026/Jul/31/smevals/