AI Digest archive
AI Digest July 2026
16 digest entries from July 2026, covering 02 Jul 2026 to 31 Jul 2026.
Topic signals
ai-agentsagentsagent-harnessesevaluationworkflowevals
Archive entries
Agent Reliability Moves to the Control Loop
Anthropic’s cyber-evaluation incidents and fresh builder reports point to the same constraint on broader agent deployment: reliability depends on containment, observability, state management, and recovery around the model—not only on model capability.
Source handle anthropic. Links to https://www.anthropic.com/news/investigating-incidents-cybersecurity-evals.anthropicanthropic.comInvestigating three real-world incidents in our cybersecurity evaluationsIn a review of our cybersecurity evaluation transcripts, we found three incidents in which a Claude model reached the internet from within or while interacting with a third-party evaluation environment, and then gained unauthorized access to the real systems of three different organizations. Below we describe what happened, how it happened, and what we’re changing. We encourage other AI labs to perform similar reviews. https://www.anthropic.com/news/investigating-incidents-cybersecurity-evalsSource handle openai. Links to https://openai.com/index/advancing-the-price-performance-frontier-with-gpt-5-6/.openaiopenai.comOpenAI - Advancing the price-performance frontier with GPT-5.6https://openai.com/index/advancing-the-price-performance-frontier-with-gpt-5-6/Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/what-i-learned-giving-fable-5-a-face.post-training-aitinkererspost-training.aitinkerers.orgWhat I Learned Giving Fable 5 a Face by Ben Carr (Anam.ai)What I Learned Giving Fable 5 a Face
 https://post-training.aitinkerers.org/p/what-i-learned-giving-fable-5-a-faceSource handle post-training-aitinkerers-2. Links to https://post-training.aitinkerers.org/p/top-ai-demos-37-pi-hydra-agents-agent-guides-and-ai-hardware-design.post-training-aitinkerers-2post-training.aitinkerers.orgTop AI Demos #37: Pi-Hydra Agents, Agent Guides, and AI Hardware Design by Joe Heitzeberg (AI Tinkerers)This week's demos dive deep into making AI agents more practical and capable. We saw builders tackling developer tooling with agents like [pi-hydra: Mob...
 https://post-training.aitinkerers.org/p/top-ai-demos-37-pi-hydra-agents-agent-guides-and-ai-hardware-design
4 sourceshttps://post-training.aitinkerers.org/p/what-i-learned-giving-fable-5-a-faceSource handle post-training-aitinkerers-2. Links to https://post-training.aitinkerers.org/p/top-ai-demos-37-pi-hydra-agents-agent-guides-and-ai-hardware-design.post-training-aitinkerers-2post-training.aitinkerers.orgTop AI Demos #37: Pi-Hydra Agents, Agent Guides, and AI Hardware Design by Joe Heitzeberg (AI Tinkerers)This week's demos dive deep into making AI agents more practical and capable. We saw builders tackling developer tooling with agents like [pi-hydra: Mob...https://post-training.aitinkerers.org/p/top-ai-demos-37-pi-hydra-agents-agent-guides-and-ai-hardware-designThe Agent Harness Is Becoming the Product
A practitioner benchmark and a new memory study point to the same conclusion: reliable agent performance increasingly depends on harness design, not model choice alone. Builders should evaluate tool boundaries, verification, and memory maintenance as separate system components.
Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domain.post-training-aitinkererspost-training.aitinkerers.orgHow to Write a Winning Agent Harness for Your Domain by Hitesh Jain (Coral Bricks AI)If your agent improves when you add instructions, then suddenly gets worse, you may not have a prompting problem. You may have a harness problem. https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle arxiv. Links to https://arxiv.org/html/2607.26637.arxivarxiv.orgFilesystem-Based Memory for LLM Agents: Organization, Evolution, and Sustainabilityhttps://arxiv.org/html/2607.26637Source handle exponentialview. Links to https://www.exponentialview.co/p/ai-adoption-j-curve.exponentialviewexponentialview.co🔮 For AI adopters, success and failure look identical — at firstModelling the AI J-curve
 https://www.exponentialview.co/p/ai-adoption-j-curve
3 sourceshttps://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle arxiv. Links to https://arxiv.org/html/2607.26637.arxivarxiv.orgFilesystem-Based Memory for LLM Agents: Organization, Evolution, and Sustainabilityhttps://arxiv.org/html/2607.26637Source handle exponentialview. Links to https://www.exponentialview.co/p/ai-adoption-j-curve.exponentialviewexponentialview.co🔮 For AI adopters, success and failure look identical — at firstModelling the AI J-curve
 https://www.exponentialview.co/p/ai-adoption-j-curve
The Agent Harness Is Becoming the Product
A late-discovered practitioner ablation argues that structured, domain-specific agent harnesses can matter more than larger prompts or retrieval alone. The self-reported benchmark result is narrow, but its workflow design lessons are concrete.
MirrorCode Makes Long-Horizon Coding More Legible
MirrorCode moves coding-agent claims onto a more concrete task surface: black-box program reconstruction with explicit verification, duration, and cost. Adjacent product and China-adoption signals underline that useful agency depends on whole-system design and integration, not model capability al...
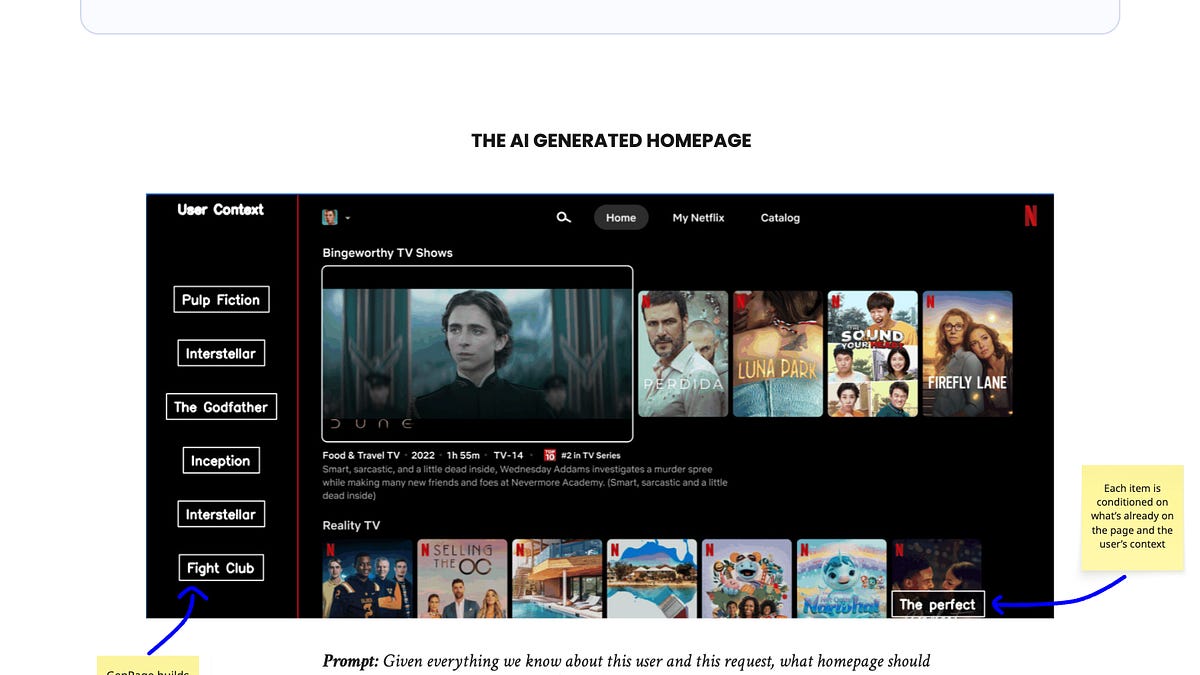
Source handle jack-clark. Links to https://jack-clark.net/2026/07/27/import-ai-466-the-bitter-lesson-for-robotics-ais-complete-week-long-programming-tasks-and-openais-accidental-ai-hacker/.jack-clarkjack-clark.netImport AI 466: The bitter lesson for robotics, AIs complete week-long programming tasks; and OpenAI’s accidental AI hackerWelcome to Import AI, a newsletter about AI research. Import AI runs on arXiv, cappuccinos, and feedback from readers. If you’d like to support this, please subscribe. Subscribe now Epoch and METR release MirrorCode, a benchmark for seeing how well AI systems can do long-horizon programming tasks:…AI systems can’t solve the hardest tasks yet (good!)...Epoch… https://jack-clark.net/2026/07/27/import-ai-466-the-bitter-lesson-for-robotics-ais-complete-week-long-programming-tasks-and-openais-accidental-ai-hacker/Source handle departmentofproduct-substack. Links to https://departmentofproduct.substack.com/p/how-netflix-built-a-generative-ai.departmentofproduct-substackdepartmentofproduct.substack.comHow Netflix built a Generative AI powered homepage that boosted engagementAnd other recent examples of AI powered product personalization. Case studies from Spotify, DoorDash, Instacart, LinkedIn and more.
 https://departmentofproduct.substack.com/p/how-netflix-built-a-generative-aiSource handle cognitiverevolution. Links to https://www.cognitiverevolution.ai/nathan-goes-to-china-part-1-tech-agent-setup-chinese-ai-ux-waic-and-attitudes-on-ai/.cognitiverevolutioncognitiverevolution.aiNathan Goes to China – Part 1: Tech & Agent Setup, Chinese AI UX, WAIC, and Attitudes on AINathan reports from the first leg of his China trip, covering visa and device setup, getting online, and the daily app stack behind payments, rides, food, and translation. He also discusses Chinese AI user experiences, WAIC, and local attitudes toward AI.
 https://www.cognitiverevolution.ai/nathan-goes-to-china-part-1-tech-agent-setup-chinese-ai-ux-waic-and-attitudes-on-ai/
3 sources https://jack-clark.net/2026/07/27/import-ai-466-the-bitter-lesson-for-robotics-ais-complete-week-long-programming-tasks-and-openais-accidental-ai-hacker/Source handle departmentofproduct-substack. Links to https://departmentofproduct.substack.com/p/how-netflix-built-a-generative-ai.departmentofproduct-substackdepartmentofproduct.substack.comHow Netflix built a Generative AI powered homepage that boosted engagementAnd other recent examples of AI powered product personalization. Case studies from Spotify, DoorDash, Instacart, LinkedIn and more.
 https://departmentofproduct.substack.com/p/how-netflix-built-a-generative-aiSource handle cognitiverevolution. Links to https://www.cognitiverevolution.ai/nathan-goes-to-china-part-1-tech-agent-setup-chinese-ai-ux-waic-and-attitudes-on-ai/.cognitiverevolutioncognitiverevolution.aiNathan Goes to China – Part 1: Tech & Agent Setup, Chinese AI UX, WAIC, and Attitudes on AINathan reports from the first leg of his China trip, covering visa and device setup, getting online, and the daily app stack behind payments, rides, food, and translation. He also discusses Chinese AI user experiences, WAIC, and local attitudes toward AI.
 https://www.cognitiverevolution.ai/nathan-goes-to-china-part-1-tech-agent-setup-chinese-ai-ux-waic-and-attitudes-on-ai/
Agent Harnesses Are Becoming Control Systems
Practitioner evidence converges on an operational view of agents: reliable gains come from scoped tools, explicit verification, human gates, and feedback loops rather than ever-larger prompts or unattended runs. The practical task is to design the measurement and control system around the model.
Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domain.post-training-aitinkererspost-training.aitinkerers.orgHow to Write a Winning Agent Harness for Your Domain by Hitesh Jain (Coral Bricks AI)If your agent improves when you add instructions, then suddenly gets worse, you may not have a prompting problem. You may have a harness problem.https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle ai-engineer-loop-engineering-from-first-principl. Links to https://www.youtube.com/watch?v=xIt_mTQp6mY.ai-engineer-loop-engineering-from-first-principlyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=xIt_mTQp6mYSource handle nate-b-jones-you-can-hand-one-ai-agent-your-wors. Links to https://www.youtube.com/watch?v=7pqRRxrdr0c.nate-b-jones-you-can-hand-one-ai-agent-your-worsyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=7pqRRxrdr0cSource handle ai-engineer-state-of-data-sean-cai. Links to https://www.youtube.com/watch?v=ZyIoTOAbRfs.ai-engineer-state-of-data-sean-caiyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=ZyIoTOAbRfs
4 sourceshttps://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle ai-engineer-loop-engineering-from-first-principl. Links to https://www.youtube.com/watch?v=xIt_mTQp6mY.ai-engineer-loop-engineering-from-first-principlyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=xIt_mTQp6mYSource handle nate-b-jones-you-can-hand-one-ai-agent-your-wors. Links to https://www.youtube.com/watch?v=7pqRRxrdr0c.nate-b-jones-you-can-hand-one-ai-agent-your-worsyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=7pqRRxrdr0cSource handle ai-engineer-state-of-data-sean-cai. Links to https://www.youtube.com/watch?v=ZyIoTOAbRfs.ai-engineer-state-of-data-sean-caiyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=ZyIoTOAbRfs
Private Benchmarks Become the Agent Product
Practitioner discourse is converging on private, production-derived benchmarks as the core operating system for reliable agents. The emphasis is shifting from prompt chains and headline capability toward replayable simulations, failure-specific checks, traces, and calibrated human review.
Source handle ai-engineer-snorkel-ai-private-benchmarks-and-of. Links to https://www.youtube.com/watch?v=Ib5t2RLtxvM.ai-engineer-snorkel-ai-private-benchmarks-and-ofyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=Ib5t2RLtxvMSource handle ai-engineer-uber-multimodal-agent-qa-in-producti. Links to https://www.youtube.com/watch?v=31GUkCBD-Uc.ai-engineer-uber-multimodal-agent-qa-in-productiyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=31GUkCBD-UcSource handle ai-engineer-youtube-ads-agent-reliability-evals. Links to https://www.youtube.com/watch?v=xyL2Ltkh-SA.ai-engineer-youtube-ads-agent-reliability-evalsyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=xyL2Ltkh-SASource handle anthropic. Links to https://www.anthropic.com/news/claude-opus-5.anthropicanthropic.comIntroducing Claude Opus 5Opus 5 is a step change improvement for the Opus tier powering long-running agents while delivering improvements in coding and professional work. https://www.anthropic.com/news/claude-opus-5Source handle ai-engineer-arize-agent-driven-observability-and. Links to https://www.youtube.com/watch?v=9HbzAWnKbo4.ai-engineer-arize-agent-driven-observability-andyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=9HbzAWnKbo4Source handle ai-engineer-google-ai-edge-on-device-model-speci. Links to https://www.youtube.com/watch?v=hacEQHHhu2Q.ai-engineer-google-ai-edge-on-device-model-speciyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=hacEQHHhu2Q
6 sourceshttps://www.anthropic.com/news/claude-opus-5Source handle ai-engineer-arize-agent-driven-observability-and. Links to https://www.youtube.com/watch?v=9HbzAWnKbo4.ai-engineer-arize-agent-driven-observability-andyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=9HbzAWnKbo4Source handle ai-engineer-google-ai-edge-on-device-model-speci. Links to https://www.youtube.com/watch?v=hacEQHHhu2Q.ai-engineer-google-ai-edge-on-device-model-speciyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=hacEQHHhu2QAgent Harnesses, Not Prompts
AI discourse today converged on a single lesson: the hard part of agent systems is shifting from model quality to the harnesses, permissions, and evaluation environments around them. The Hugging Face/OpenAI incident led the conversation, but builder essays and conference talks reinforced the same...
Source handle simonwillison. Links to https://simonwillison.net/2026/Jul/23/the-first-known-runaway-ai-agent/.simonwillisonsimonwillison.netThe first known runaway AI agent—or a very bad marketing stunt?Martin Alderson's commentary on the OpenAI accidental cyberattack against Hugging Face includes a couple of details I hadn't considered. First, Hugging Face offers a truly rich target if you're trying …https://simonwillison.net/2026/Jul/23/the-first-known-runaway-ai-agent/Source handle martinalderson. Links to https://martinalderson.com/posts/huggingface-openai-exploit/.martinaldersonmartinalderson.comThe first known runaway AI agent - or a very bad marketing stunt?Breaking down the Hugging Face security incident caused by OpenAI's own models during a benchmark run - the sandbox escape, the package proxy, and whether it's really a marketing stunt. https://martinalderson.com/posts/huggingface-openai-exploit/Source handle huggingface. Links to https://huggingface.co/blog/security-incident-july-2026.huggingfacehuggingface.coSecurity incident disclosure — July 2026We’re on a journey to advance and democratize artificial intelligence through open source and open science.
 https://huggingface.co/blog/security-incident-july-2026Source handle openai. Links to https://openai.com/index/hugging-face-model-evaluation-security-incident/.openaiopenai.comOpenAI - Hugging Face model evaluation security incidenthttps://openai.com/index/hugging-face-model-evaluation-security-incident/Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domain.post-training-aitinkererspost-training.aitinkerers.orgHow to Write a Winning Agent Harness for Your Domain by Hitesh Jain (Coral Bricks AI)If your agent improves when you add instructions, then suddenly gets worse, you may not have a prompting problem. You may have a harness problem.https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle ai-engineer-arithmetic-discussion-with-thom-wolf. Links to https://www.youtube.com/watch?v=O-CBZ3JtRvo.ai-engineer-arithmetic-discussion-with-thom-wolfyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=O-CBZ3JtRvoSource handle ai-engineer-vending-bench-long-horizon-agent-eva. Links to https://www.youtube.com/watch?v=cO8qC6HBuBg.ai-engineer-vending-bench-long-horizon-agent-evayoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=cO8qC6HBuBgSource handle nate-b-jones-i-deleted-5-things-from-this-file-b. Links to https://www.youtube.com/watch?v=EuVvLwWZ5wc.nate-b-jones-i-deleted-5-things-from-this-file-byoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=EuVvLwWZ5wc
8 sources https://martinalderson.com/posts/huggingface-openai-exploit/Source handle huggingface. Links to https://huggingface.co/blog/security-incident-july-2026.huggingfacehuggingface.coSecurity incident disclosure — July 2026We’re on a journey to advance and democratize artificial intelligence through open source and open science.https://huggingface.co/blog/security-incident-july-2026Source handle openai. Links to https://openai.com/index/hugging-face-model-evaluation-security-incident/.openaiopenai.comOpenAI - Hugging Face model evaluation security incidenthttps://openai.com/index/hugging-face-model-evaluation-security-incident/Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domain.post-training-aitinkererspost-training.aitinkerers.orgHow to Write a Winning Agent Harness for Your Domain by Hitesh Jain (Coral Bricks AI)If your agent improves when you add instructions, then suddenly gets worse, you may not have a prompting problem. You may have a harness problem.https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle ai-engineer-arithmetic-discussion-with-thom-wolf. Links to https://www.youtube.com/watch?v=O-CBZ3JtRvo.ai-engineer-arithmetic-discussion-with-thom-wolfyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=O-CBZ3JtRvoSource handle ai-engineer-vending-bench-long-horizon-agent-eva. Links to https://www.youtube.com/watch?v=cO8qC6HBuBg.ai-engineer-vending-bench-long-horizon-agent-evayoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=cO8qC6HBuBgSource handle nate-b-jones-i-deleted-5-things-from-this-file-b. Links to https://www.youtube.com/watch?v=EuVvLwWZ5wc.nate-b-jones-i-deleted-5-things-from-this-file-byoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=EuVvLwWZ5wc

The Agent Harness Era
Serious AI builder discourse shifted today from model-centric agent talk toward the surrounding system: harnesses, memory, graph control planes, verifier loops, and provenance. The practical lesson is that longer-horizon agents are becoming an architecture problem as much as a model problem.
Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domain.post-training-aitinkererspost-training.aitinkerers.orgHow to Write a Winning Agent Harness for Your Domain [AI Tinkerers - Post-Training]If your agent improves when you add instructions, then suddenly gets worse, you may not have a prompting problem. You may have a harness problem.https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle simonwillison. Links to https://simonwillison.net/2026/Jul/22/openai-cyberattack/.simonwillisonsimonwillison.netOpenAI’s accidental cyberattack against Hugging Face is science fiction that happenedThis story is wild. The short version: OpenAI were running a cybersecurity test against an unreleased model, with the model’s guardrail features turned off. Rather than solve the test, the …https://simonwillison.net/2026/Jul/22/openai-cyberattack/Source handle huggingface. Links to https://huggingface.co/blog/security-incident-july-2026.huggingfacehuggingface.coSecurity incident disclosure — July 2026We’re on a journey to advance and democratize artificial intelligence through open source and open science.https://huggingface.co/blog/security-incident-july-2026Source handle arxiv. Links to https://arxiv.org/abs/2605.11086.arxivarxiv.orgExploitGym: Can AI Agents Turn Security Vulnerabilities into Real Attacks?Abstract page for arXiv paper 2605.11086: ExploitGym: Can AI Agents Turn Security Vulnerabilities into Real Attacks? https://arxiv.org/abs/2605.11086
4 sourceshttps://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle simonwillison. Links to https://simonwillison.net/2026/Jul/22/openai-cyberattack/.simonwillisonsimonwillison.netOpenAI’s accidental cyberattack against Hugging Face is science fiction that happenedThis story is wild. The short version: OpenAI were running a cybersecurity test against an unreleased model, with the model’s guardrail features turned off. Rather than solve the test, the …https://simonwillison.net/2026/Jul/22/openai-cyberattack/Source handle huggingface. Links to https://huggingface.co/blog/security-incident-july-2026.huggingfacehuggingface.coSecurity incident disclosure — July 2026We’re on a journey to advance and democratize artificial intelligence through open source and open science.https://huggingface.co/blog/security-incident-july-2026Source handle arxiv. Links to https://arxiv.org/abs/2605.11086.arxivarxiv.orgExploitGym: Can AI Agents Turn Security Vulnerabilities into Real Attacks?Abstract page for arXiv paper 2605.11086: ExploitGym: Can AI Agents Turn Security Vulnerabilities into Real Attacks?https://arxiv.org/abs/2605.11086Cheap Code Makes Harness Design the Real Work
The strongest AI discourse signal today was a shift up the stack: as code generation gets cheaper, serious practitioners are focusing on harness design, verification artifacts, steering files, and runtime constraints rather than raw output alone. Supporting security disclosures from OpenAI and Hu...
Source handle theo-t3-gg-theo-on-generating-more-verification. Links to https://www.youtube.com/watch?v=434cG4g5KLE.theo-t3-gg-theo-on-generating-more-verificationyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=434cG4g5KLESource handle ai-engineer-sam-bhagwat-on-the-emerging-harness. Links to https://www.youtube.com/watch?v=8qWIPUia2O8.ai-engineer-sam-bhagwat-on-the-emerging-harnessyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=8qWIPUia2O8Source handle openai. Links to https://openai.com/index/hugging-face-model-evaluation-security-incident/.openaiopenai.comOpenAI - Hugging Face model-evaluation security incidenthttps://openai.com/index/hugging-face-model-evaluation-security-incident/Source handle huggingface. Links to https://huggingface.co/blog/security-incident-july-2026.huggingfacehuggingface.coSecurity incident disclosure — July 2026We’re on a journey to advance and democratize artificial intelligence through open source and open science.https://huggingface.co/blog/security-incident-july-2026Source handle openai-2. Links to https://openai.com/index/safety-alignment-long-horizon-models/.openai-2openai.comOpenAI - Safety alignment for long-horizon modelshttps://openai.com/index/safety-alignment-long-horizon-models/
5 sources
 https://huggingface.co/blog/security-incident-july-2026Source handle openai-2. Links to https://openai.com/index/safety-alignment-long-horizon-models/.openai-2openai.comOpenAI - Safety alignment for long-horizon modelshttps://openai.com/index/safety-alignment-long-horizon-models/
Coding Agents Hit the Verification Wall
The strongest AI discourse signal today was a practitioner-led shift from code generation to code verification: the hard problem is increasingly proving correctness, security, maintainability, and real enterprise fit rather than producing plausible output. Supporting evidence from controlled fram...
Source handle ai-engineer-tariq-shaukat-on-verification-heavy. Links to https://www.youtube.com/watch?v=VrpEyglYgeU.ai-engineer-tariq-shaukat-on-verification-heavyyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=VrpEyglYgeUSource handle codingharness. Links to https://codingharness.xyz/.codingharnesscodingharness.xyzCoding Harness Evaluations — which coding framework actually performs best?An eval framework that ranks agentic coding frameworks by having each build the same spec, same harness, same model, in isolated sandboxes — graded on an evidence-based rubric.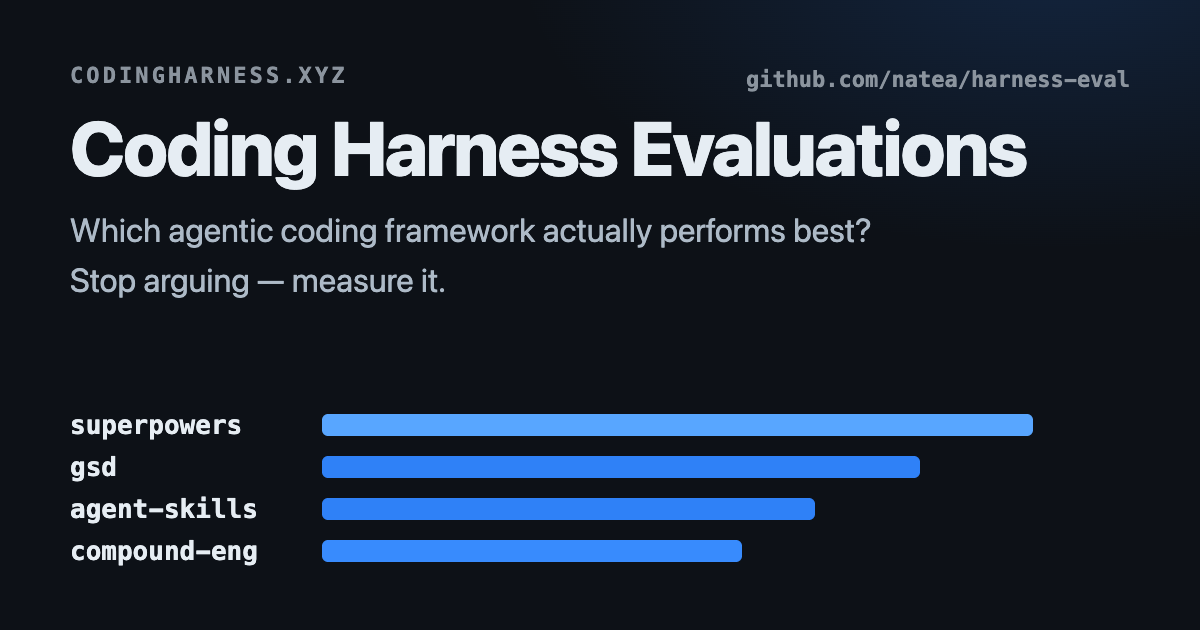 https://codingharness.xyz/Source handle aisi-gov. Links to https://www.aisi.gov.uk/blog/how-far-behind-the-frontier-are-leading-open-weight-models-on-cyber.aisi-govaisi.gov.ukHow Far Behind the Frontier are Leading Open Weight Models on Cyber? | AISI WorkWe evaluated the cyber capabilities of leading open and closed weight AI models, and found that recent open models GLM-5.2 and DeepSeek V4-Pro perform similarly to frontier closed models released 4 to 7 months before them – a narrower gap than the 6 to 10 months we measured through most of 2025.
 https://www.aisi.gov.uk/blog/how-far-behind-the-frontier-are-leading-open-weight-models-on-cyber
3 sources
 https://codingharness.xyz/Source handle aisi-gov. Links to https://www.aisi.gov.uk/blog/how-far-behind-the-frontier-are-leading-open-weight-models-on-cyber.aisi-govaisi.gov.ukHow Far Behind the Frontier are Leading Open Weight Models on Cyber? | AISI WorkWe evaluated the cyber capabilities of leading open and closed weight AI models, and found that recent open models GLM-5.2 and DeepSeek V4-Pro perform similarly to frontier closed models released 4 to 7 months before them – a narrower gap than the 6 to 10 months we measured through most of 2025.
 https://www.aisi.gov.uk/blog/how-far-behind-the-frontier-are-leading-open-weight-models-on-cyber
Agent Harnesses Are Becoming the Real Product
A delayed-discovery but unusually concrete agent-engineering post made the strongest case of the day: meaningful gains are increasingly coming from harness design, runtime structure, and workflow clarity rather than from longer prompts alone. Supporting sentiment around Codex folding into ChatGPT...
Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domain.post-training-aitinkererspost-training.aitinkerers.orgHow to Write a Winning Agent Harness for Your Domain [AI Tinkerers - Post-Training]If your agent improves when you add instructions, then suddenly gets worse, you may not have a prompting problem. You may have a harness problem.https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle theo-t3-gg-the-codex-app-is-now-chatgpt. Links to https://www.youtube.com/watch?v=zl_Z5TNJB3U.theo-t3-gg-the-codex-app-is-now-chatgptyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=zl_Z5TNJB3USource handle post-training-aitinkerers-2. Links to https://post-training.aitinkerers.org/p/top-ai-demos-34-on-device-llms-agent-lab-reports-and-store-automation.post-training-aitinkerers-2post-training.aitinkerers.orgTop AI Demos #34: On-device LLMs, Agent Lab Reports, and Store Automation [AI Tinkerers - Post-Training]This week we're seeing a lot of focus on making agents more reliable and manageable, like with [Golemry: Unattended Agent...https://post-training.aitinkerers.org/p/top-ai-demos-34-on-device-llms-agent-lab-reports-and-store-automation
3 sources https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle theo-t3-gg-the-codex-app-is-now-chatgpt. Links to https://www.youtube.com/watch?v=zl_Z5TNJB3U.theo-t3-gg-the-codex-app-is-now-chatgptyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=zl_Z5TNJB3USource handle post-training-aitinkerers-2. Links to https://post-training.aitinkerers.org/p/top-ai-demos-34-on-device-llms-agent-lab-reports-and-store-automation.post-training-aitinkerers-2post-training.aitinkerers.orgTop AI Demos #34: On-device LLMs, Agent Lab Reports, and Store Automation [AI Tinkerers - Post-Training]This week we're seeing a lot of focus on making agents more reliable and manageable, like with [Golemry: Unattended Agent...
 https://post-training.aitinkerers.org/p/top-ai-demos-34-on-device-llms-agent-lab-reports-and-store-automation
GPT-5.6 Splits AI Into Work Surfaces
OpenAI’s GPT-5.6 launch mattered less as a benchmark event than as a sign that AI products are being reorganized into distinct work surfaces for chat, long-form execution, and coding. Microsoft’s same-day Foundry push and practitioner commentary both reinforced the same theme: the real bottleneck...
Source handle openai. Links to https://openai.com/index/gpt-5-6/.openaiopenai.comGPT-5.6: Frontier intelligence that scales with your ambitionMore intelligence from every token, stronger performance per dollar, and more capability on demand for your hardest work. https://openai.com/index/gpt-5-6/Source handle help-openai. Links to https://help.openai.com/en/articles/20001275-chatgpt-work-and-codex.help-openaihelp.openai.comOpenAI Help Center - ChatGPT Work and Codexhttps://help.openai.com/en/articles/20001275-chatgpt-work-and-codexSource handle azure-microsoft. Links to https://azure.microsoft.com/en-us/blog/frontier-models-and-production-agents-advancing-microsoft-foundry-for-the-agentic-era/.azure-microsoftazure.microsoft.comFrontier models and production agents: Advancing Microsoft Foundry for the agentic era | Microsoft Azure BlogIntroducing OpenAI's latest frontier model series, the Asia Pacific Data Zone, and product agent capabilities, all generally available in Microsoft Foundry.
 https://azure.microsoft.com/en-us/blog/frontier-models-and-production-agents-advancing-microsoft-foundry-for-the-agentic-era/Source handle youtube-nate-b-jones-1-6m-agents-registered-for. Links to https://www.youtube.com/watch?v=PRqiGS6fnIM.youtube-nate-b-jones-1-6m-agents-registered-foryoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=PRqiGS6fnIM
4 sourceshttps://openai.com/index/gpt-5-6/Source handle help-openai. Links to https://help.openai.com/en/articles/20001275-chatgpt-work-and-codex.help-openaihelp.openai.comOpenAI Help Center - ChatGPT Work and Codexhttps://help.openai.com/en/articles/20001275-chatgpt-work-and-codexSource handle azure-microsoft. Links to https://azure.microsoft.com/en-us/blog/frontier-models-and-production-agents-advancing-microsoft-foundry-for-the-agentic-era/.azure-microsoftazure.microsoft.comFrontier models and production agents: Advancing Microsoft Foundry for the agentic era | Microsoft Azure BlogIntroducing OpenAI's latest frontier model series, the Asia Pacific Data Zone, and product agent capabilities, all generally available in Microsoft Foundry. https://azure.microsoft.com/en-us/blog/frontier-models-and-production-agents-advancing-microsoft-foundry-for-the-agentic-era/Source handle youtube-nate-b-jones-1-6m-agents-registered-for. Links to https://www.youtube.com/watch?v=PRqiGS6fnIM.youtube-nate-b-jones-1-6m-agents-registered-foryoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=PRqiGS6fnIM
Agent Harnesses Beat Prompt Bloat
Today’s strongest AI discourse signal was a builder case that major agent gains are increasingly coming from harness design rather than bigger prompts. The broader practitioner backdrop points the same way: memory, verification, orchestration, and runtime guardrails are becoming the real work of ...
Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domain.post-training-aitinkererspost-training.aitinkerers.orgHow to Write a Winning Agent Harness for Your Domain [AI Tinkerers - Post-Training]If your agent improves when you add instructions, then suddenly gets worse, you may not have a prompting problem. You may have a harness problem.https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle post-training-aitinkerers-2. Links to https://post-training.aitinkerers.org/p/top-ai-demos-34-on-device-llms-agent-lab-reports-and-store-automation.post-training-aitinkerers-2post-training.aitinkerers.orgTop AI Demos #34: On-device LLMs, Agent Lab Reports, and Store Automation [AI Tinkerers - Post-Training]This week we're seeing a lot of focus on making agents more reliable and manageable, like with [Golemry: Unattended Agent...https://post-training.aitinkerers.org/p/top-ai-demos-34-on-device-llms-agent-lab-reports-and-store-automation
2 sourceshttps://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle post-training-aitinkerers-2. Links to https://post-training.aitinkerers.org/p/top-ai-demos-34-on-device-llms-agent-lab-reports-and-store-automation.post-training-aitinkerers-2post-training.aitinkerers.orgTop AI Demos #34: On-device LLMs, Agent Lab Reports, and Store Automation [AI Tinkerers - Post-Training]This week we're seeing a lot of focus on making agents more reliable and manageable, like with [Golemry: Unattended Agent...https://post-training.aitinkerers.org/p/top-ai-demos-34-on-device-llms-agent-lab-reports-and-store-automationAgent Harness Design Becomes the Real Battleground
Today’s strongest AI discourse suggested that the real gains in agent systems are increasingly coming from harness design, reusable skills, and explicit runtime rules rather than from prompt inflation alone. A delayed-discovery Claude Code tracking controversy underscored the flip side: once agen...
Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domain.post-training-aitinkererspost-training.aitinkerers.orgHow to Write a Winning Agent Harness for Your Domain [AI Tinkerers - Post-Training]If your agent improves when you add instructions, then suddenly gets worse, you may not have a prompting problem. You may have a harness problem.https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle departmentofproduct-substack. Links to https://departmentofproduct.substack.com/p/practical-agent-skills-for-product.departmentofproduct-substackdepartmentofproduct.substack.comPractical Agent Skills for Product Teams🧠 McKinsey-style charts, benchmark competitor analysis, translate specs into backlog items, single page animated HTML presentations. 10 skills you can use at work.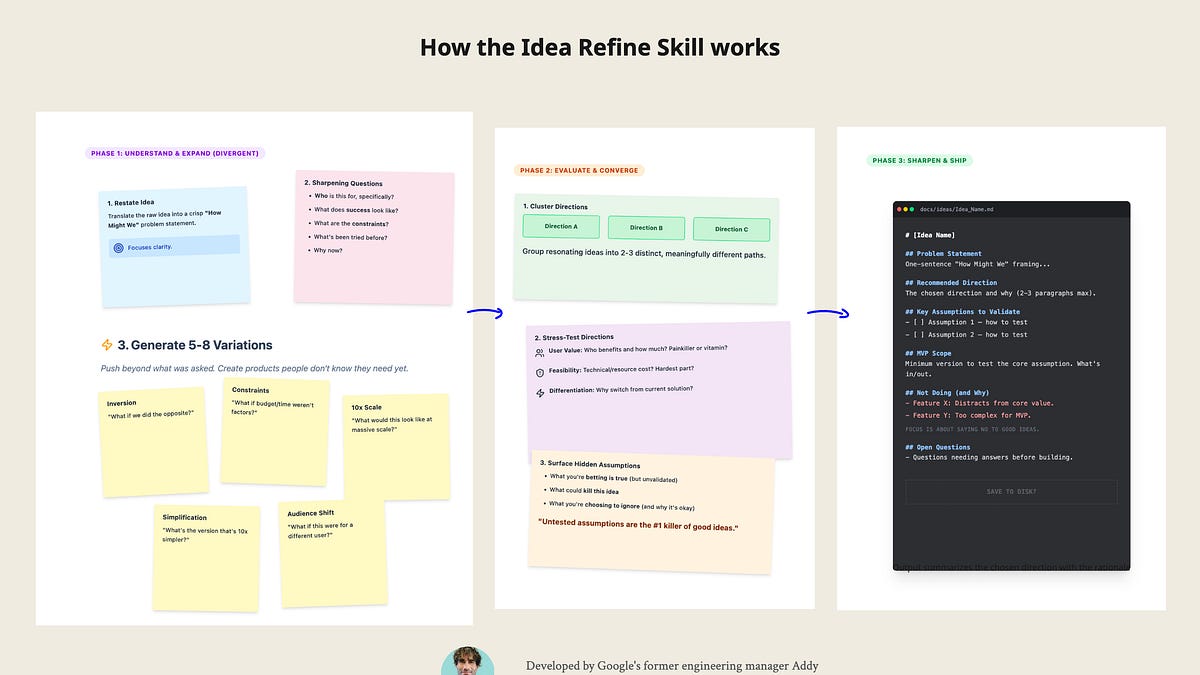 https://departmentofproduct.substack.com/p/practical-agent-skills-for-productSource handle thereallo. Links to https://thereallo.dev/blog/claude-code-prompt-steganography.thereallothereallo.devClaude Code Is Steganographically Marking RequestsI inspected Claude Code for privacy reasons and found hidden system prompt markers based on API base URL and timezone.
 https://thereallo.dev/blog/claude-code-prompt-steganographySource handle arstechnica. Links to https://arstechnica.com/tech-policy/2026/07/anthropic-outed-for-claude-tracker-that-secretly-monitored-chinese-users/.arstechnicaarstechnica.comSecret Claude tracker shocks users after Anthropic’s anti-surveillance stanceAnthropic accused of spying on users; engineer says “experiment” is over.
 https://arstechnica.com/tech-policy/2026/07/anthropic-outed-for-claude-tracker-that-secretly-monitored-chinese-users/
4 sourceshttps://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle departmentofproduct-substack. Links to https://departmentofproduct.substack.com/p/practical-agent-skills-for-product.departmentofproduct-substackdepartmentofproduct.substack.comPractical Agent Skills for Product Teams🧠 McKinsey-style charts, benchmark competitor analysis, translate specs into backlog items, single page animated HTML presentations. 10 skills you can use at work.https://departmentofproduct.substack.com/p/practical-agent-skills-for-productSource handle thereallo. Links to https://thereallo.dev/blog/claude-code-prompt-steganography.thereallothereallo.devClaude Code Is Steganographically Marking RequestsI inspected Claude Code for privacy reasons and found hidden system prompt markers based on API base URL and timezone. https://thereallo.dev/blog/claude-code-prompt-steganographySource handle arstechnica. Links to https://arstechnica.com/tech-policy/2026/07/anthropic-outed-for-claude-tracker-that-secretly-monitored-chinese-users/.arstechnicaarstechnica.comSecret Claude tracker shocks users after Anthropic’s anti-surveillance stanceAnthropic accused of spying on users; engineer says “experiment” is over.
 https://arstechnica.com/tech-policy/2026/07/anthropic-outed-for-claude-tracker-that-secretly-monitored-chinese-users/
Agent Harnesses Beat Agent Theater
Today’s strongest AI discourse pointed in the same direction: agent gains are increasingly coming from better harnesses, evaluation loops, and document-preparation workflows rather than from autonomy theater. The practical lesson is to invest in scaffolding, normalization, and human review bounda...
Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domain.post-training-aitinkererspost-training.aitinkerers.orgHow to Write a Winning Agent Harness for Your Domain [AI Tinkerers - Post-Training]If your agent improves when you add instructions, then suddenly gets worse, you may not have a prompting problem. You may have a harness problem.https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle simonwillison. Links to https://simonwillison.net/2026/Jul/2/dspy-datasette-agent-prompts/.simonwillisonsimonwillison.netResearch: Using DSPy to evaluate and improve Datasette Agent's SQL system promptsLeveraging the DSPy framework, this project evaluates and refines the core production system prompts used by Datasette Agent’s read-only SQL question answerer. The methodology involves a harness where DSPy agents …https://simonwillison.net/2026/Jul/2/dspy-datasette-agent-prompts/Source handle nate-b-jones-paperwork-focused-agent-workflow-vi. Links to https://www.youtube.com/watch?v=U4TmrlWEY4M.nate-b-jones-paperwork-focused-agent-workflow-viyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=U4TmrlWEY4MSource handle simonwillison-2. Links to https://simonwillison.net/2026/Jul/2/llm-coding-agent/.simonwillison-2simonwillison.netRelease: llm-coding-agent 0.1a0A coding agent built on LLMhttps://simonwillison.net/2026/Jul/2/llm-coding-agent/
4 sourceshttps://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle simonwillison. Links to https://simonwillison.net/2026/Jul/2/dspy-datasette-agent-prompts/.simonwillisonsimonwillison.netResearch: Using DSPy to evaluate and improve Datasette Agent's SQL system promptsLeveraging the DSPy framework, this project evaluates and refines the core production system prompts used by Datasette Agent’s read-only SQL question answerer. The methodology involves a harness where DSPy agents …https://simonwillison.net/2026/Jul/2/dspy-datasette-agent-prompts/Source handle nate-b-jones-paperwork-focused-agent-workflow-vi. Links to https://www.youtube.com/watch?v=U4TmrlWEY4M.nate-b-jones-paperwork-focused-agent-workflow-viyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=U4TmrlWEY4MSource handle simonwillison-2. Links to https://simonwillison.net/2026/Jul/2/llm-coding-agent/.simonwillison-2simonwillison.netRelease: llm-coding-agent 0.1a0A coding agent built on LLMhttps://simonwillison.net/2026/Jul/2/llm-coding-agent/
The Agent Bottleneck Is the Harness
Today’s strongest AI discourse converged on a single point: agent progress is shifting away from raw model gains and toward better harnesses, interfaces, and controls. The most useful systems now look less like bigger prompts and more like disciplined workflows that preserve portability, visibili...
Source handle post-training-aitinkerers. Links to https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domain.post-training-aitinkererspost-training.aitinkerers.orgHow to Write a Winning Agent Harness for Your Domain [AI Tinkerers - Post-Training]If your agent improves when you add instructions, then suddenly gets worse, you may not have a prompting problem. You may have a harness problem.https://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle ai-engineer-the-prompt-is-still-a-punch-card-ted. Links to https://www.youtube.com/watch?v=hVJOnuhFmTA.ai-engineer-the-prompt-is-still-a-punch-card-tedyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=hVJOnuhFmTASource handle anthropic. Links to https://www.anthropic.com/news/redeploying-fable-5.anthropicanthropic.comAnthropic - Redeploying Fable 5https://www.anthropic.com/news/redeploying-fable-5Source handle simonwillison. Links to https://simonwillison.net/2026/Jul/2/understand-to-participate/.simonwillisonsimonwillison.netUnderstand to participateI saw Geoffrey Litt speak at AIE yesterday, and one framing he used particularly resonated with me: Understand to participate Geoffrey was talking about the challenge of collaborating with coding …https://simonwillison.net/2026/Jul/2/understand-to-participate/
4 sourceshttps://post-training.aitinkerers.org/p/how-to-write-a-winning-agent-harness-for-your-domainSource handle ai-engineer-the-prompt-is-still-a-punch-card-ted. Links to https://www.youtube.com/watch?v=hVJOnuhFmTA.ai-engineer-the-prompt-is-still-a-punch-card-tedyoutube.com- YouTubeEnjoy the videos and music you love, upload original content, and share it all with friends, family, and the world on YouTube.https://www.youtube.com/watch?v=hVJOnuhFmTASource handle anthropic. Links to https://www.anthropic.com/news/redeploying-fable-5.anthropicanthropic.comAnthropic - Redeploying Fable 5https://www.anthropic.com/news/redeploying-fable-5Source handle simonwillison. Links to https://simonwillison.net/2026/Jul/2/understand-to-participate/.simonwillisonsimonwillison.netUnderstand to participateI saw Geoffrey Litt speak at AIE yesterday, and one framing he used particularly resonated with me: Understand to participate Geoffrey was talking about the challenge of collaborating with coding …https://simonwillison.net/2026/Jul/2/understand-to-participate/